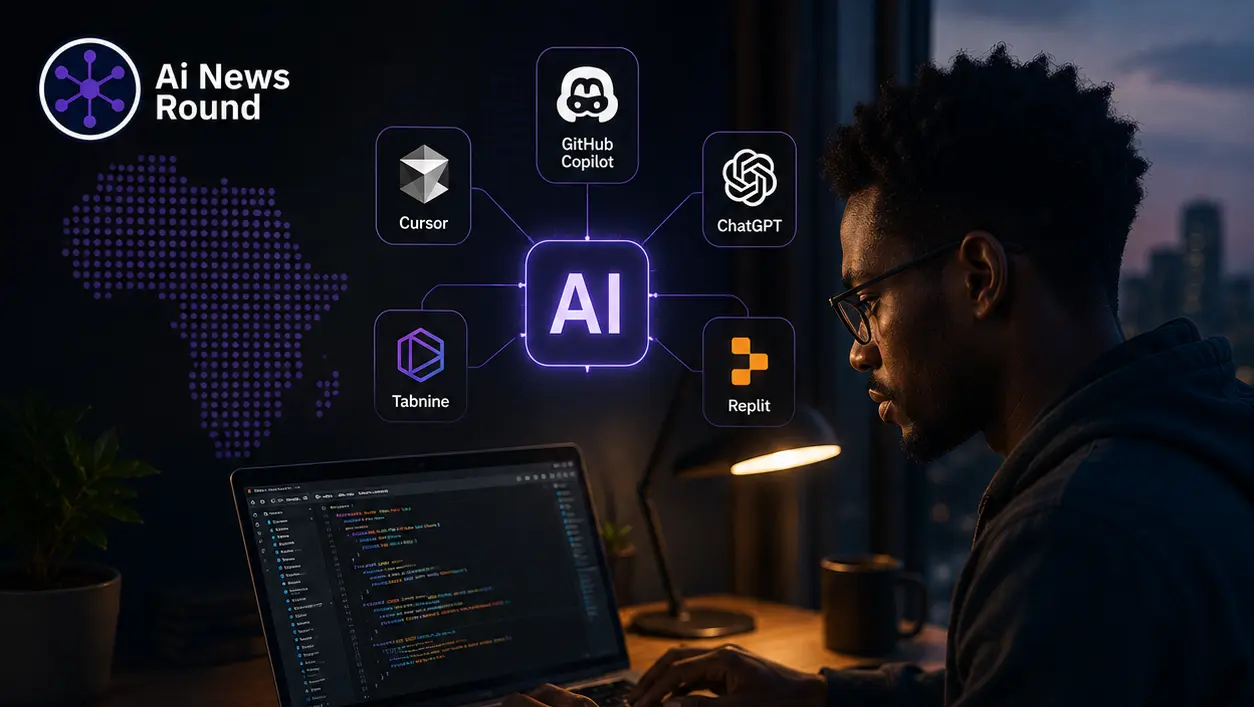
Which AI Tools Are Actually Useful for African Developers? An Honest Assessment
Most tool round-ups ignore whether you can sign up, pay, or run the thing on the connection you actually have. This one starts there.
The AI News Round editorial desk. Bylines are replaced with the reporting journalist once a story is commissioned — this account exists so the site has a working author profile before the newsroom is staffed.
Most tool round-ups ignore whether you can sign up, pay, or run the thing on the connection you actually have. This one starts there.
Benchmarks that report African language coverage tend to measure the wrong thing. What breaks is not translation quality but everything downstream of it.
The demo works. The rollout does not. What sits between them is rarely the model, and companies keep being surprised by the same four things.
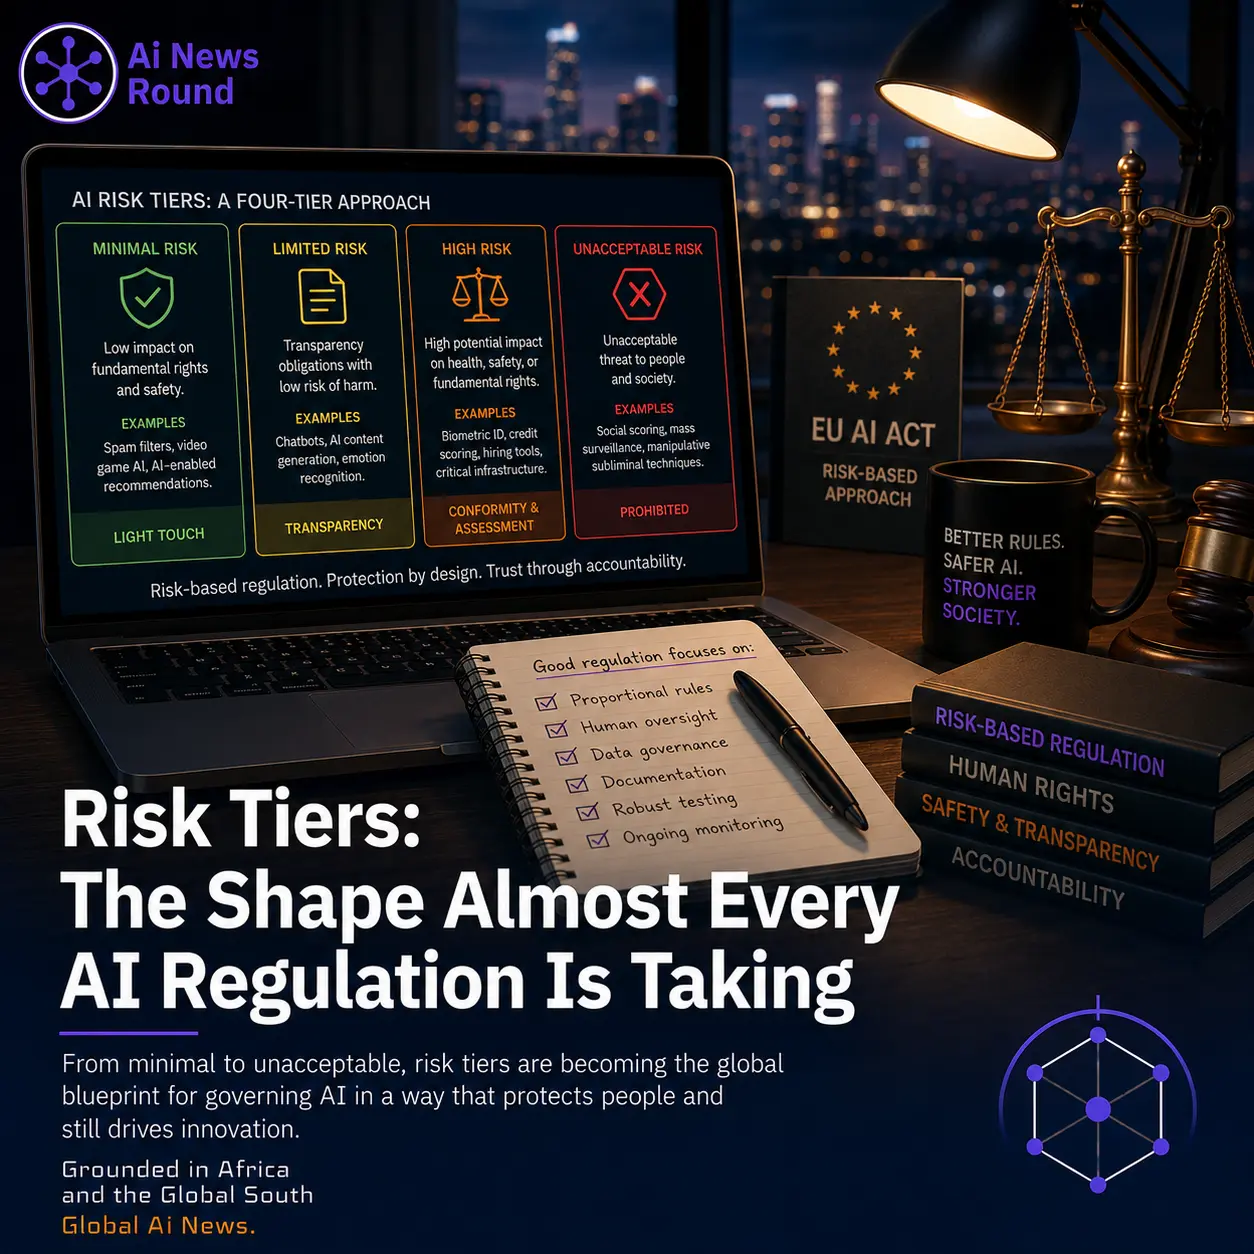
The first comprehensive AI law is now operating. Its risk-tiered structure is widely copied — including the parts that have not worked.
Context windows grew, prices fell, and the benchmark scores moved less than the marketing implies. A look at which changes are real and which are rounding errors.
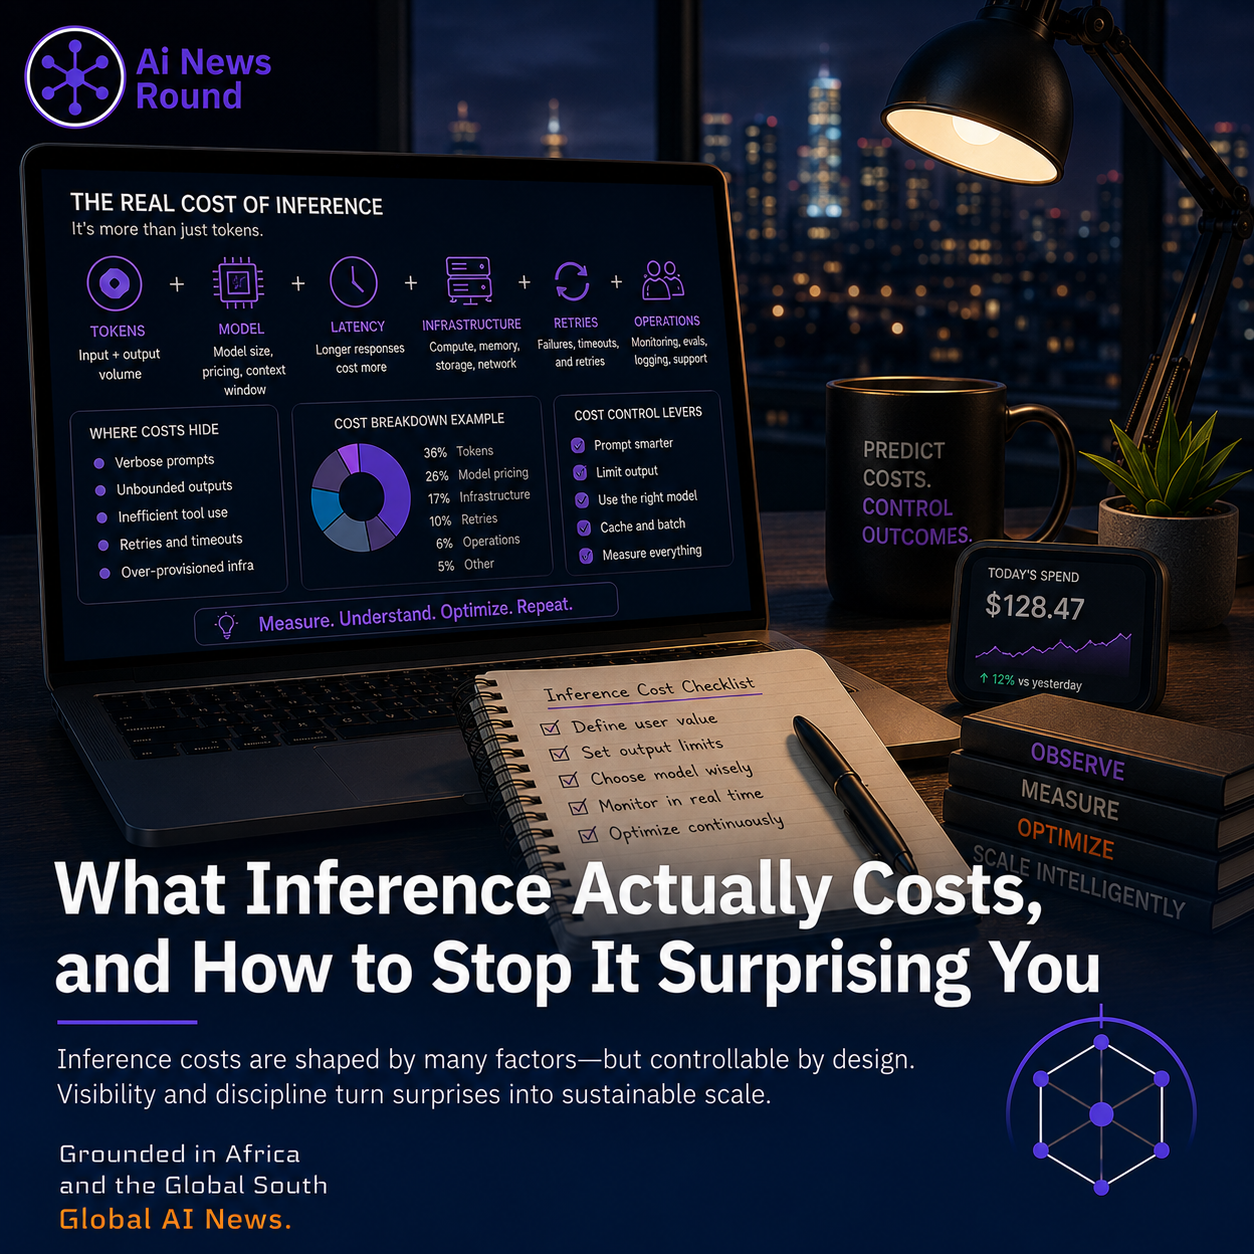
Per-token pricing looks trivial until it multiplies by traffic. The bill is controllable, and most of the control is in decisions made early.
Jurisdictions differ on the detail and agree on the structure: obligations scale with what the system is used for, not with how it was built.
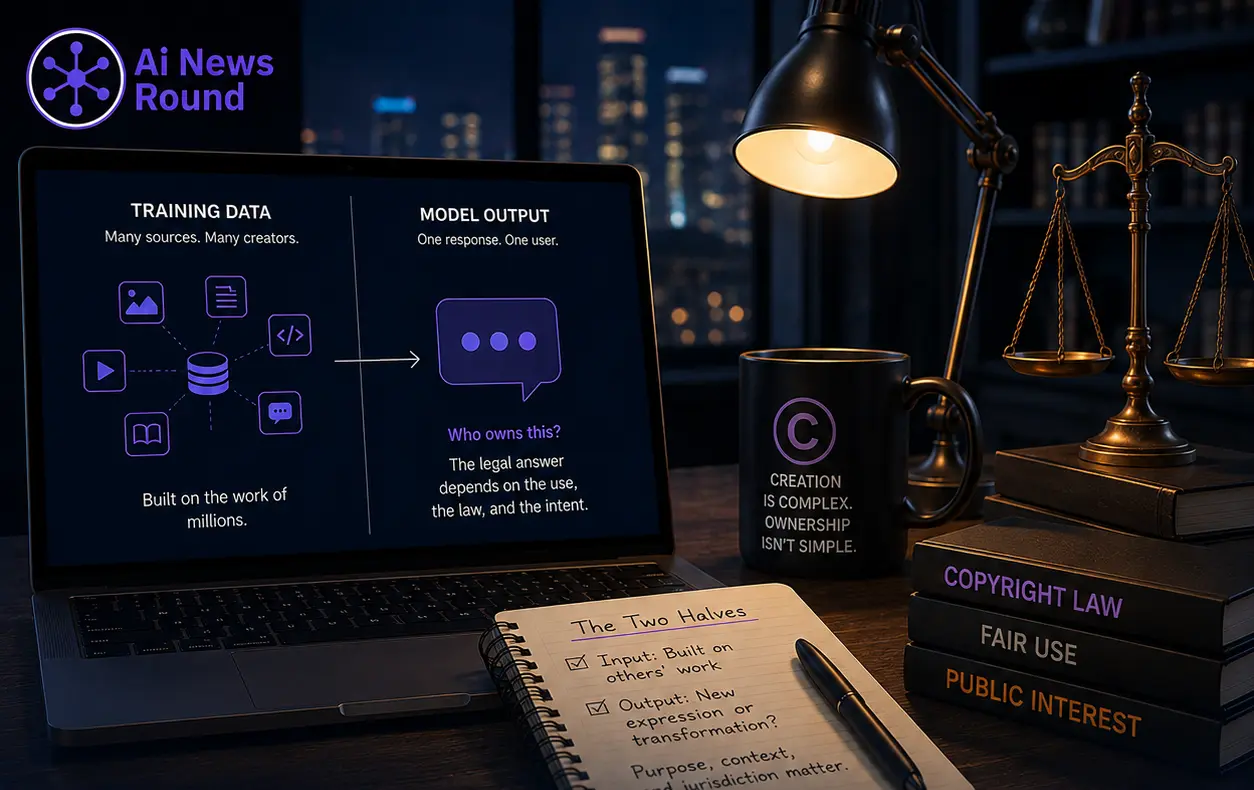
There are two separate legal arguments running, they have different answers, and conflating them is why the debate goes in circles.
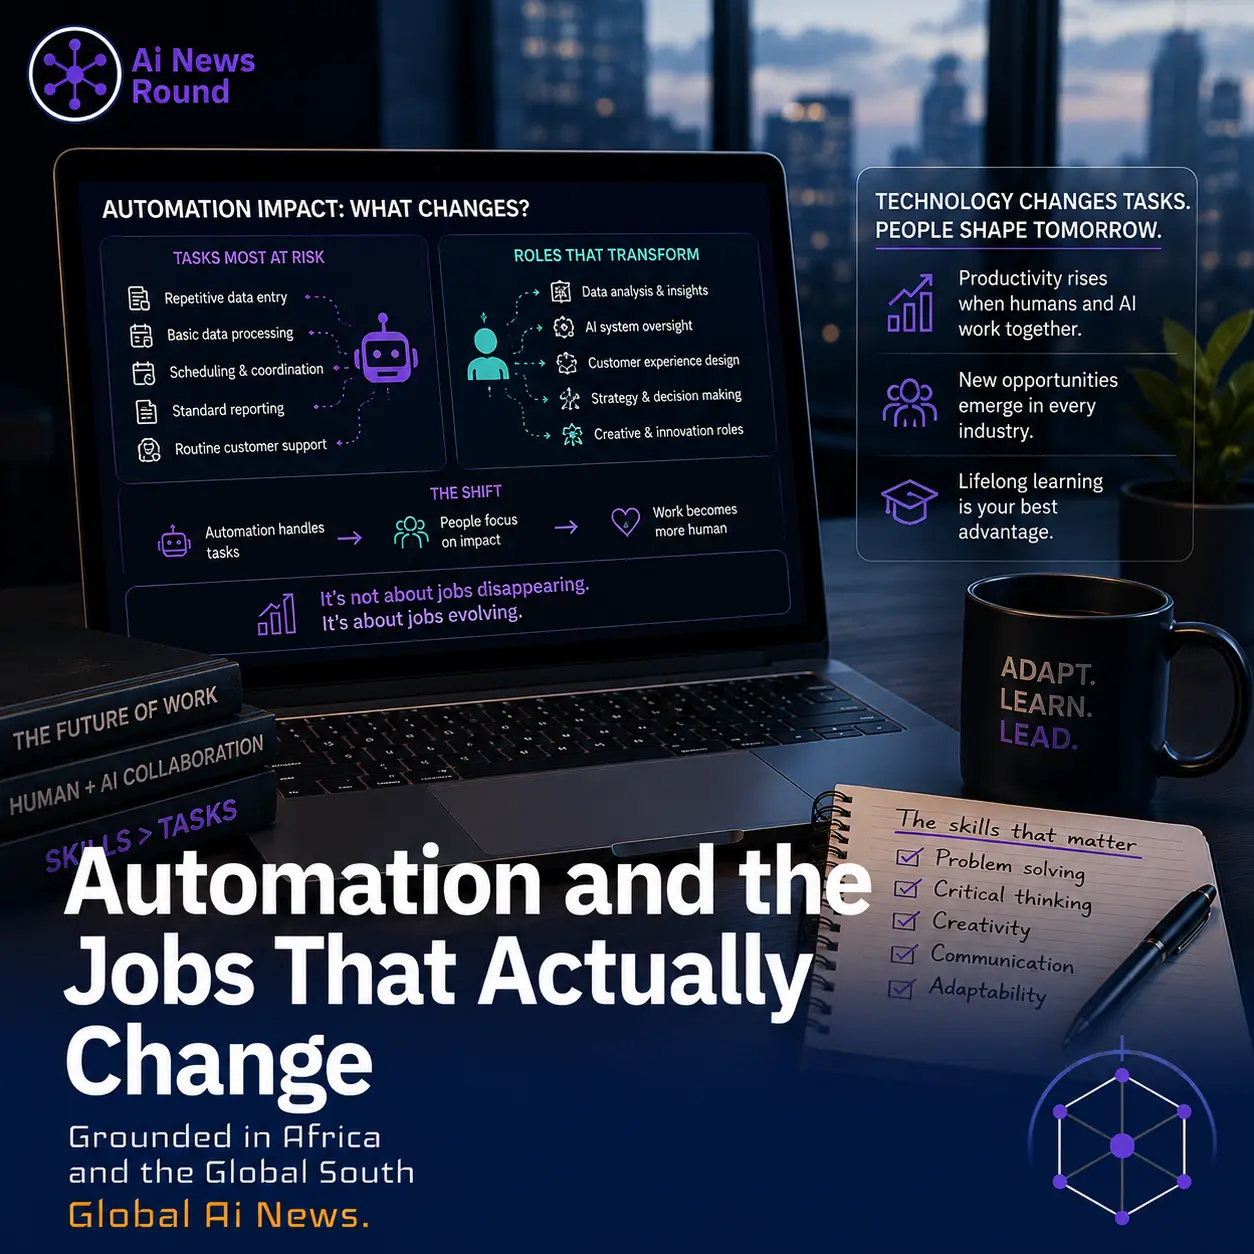
The useful unit of analysis is the task, not the occupation. Almost no job is fully automatable, and almost every job contains tasks that are.
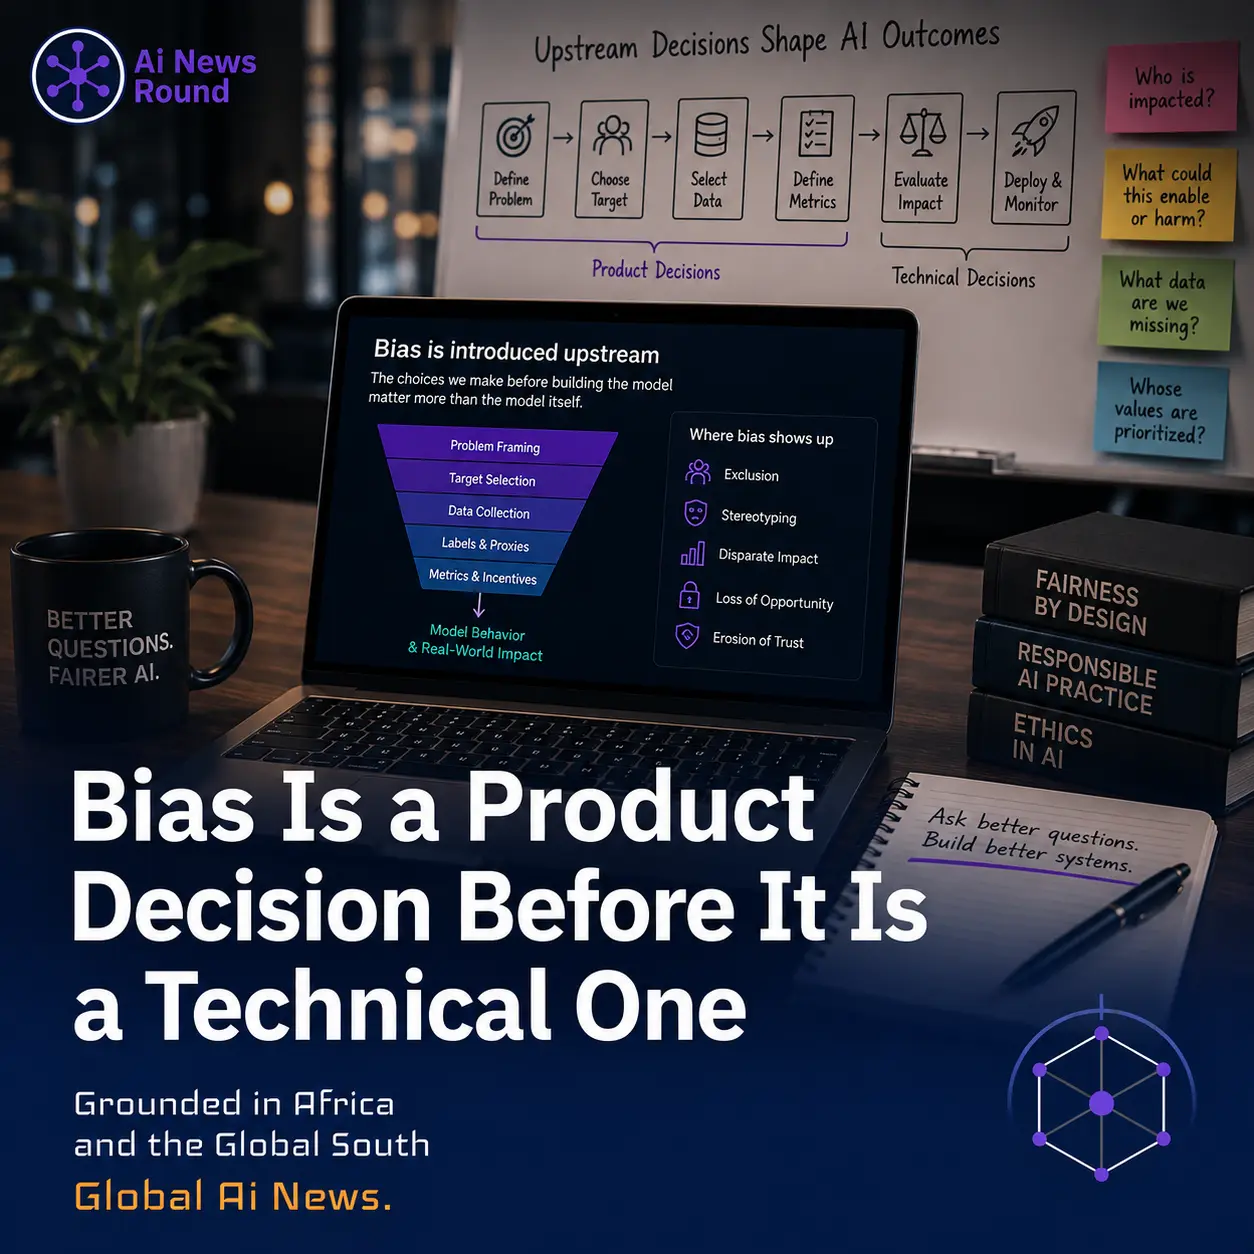
Most of the harm attributed to biased models is decided upstream: what the system is asked to predict, and what data was available to predict it from.
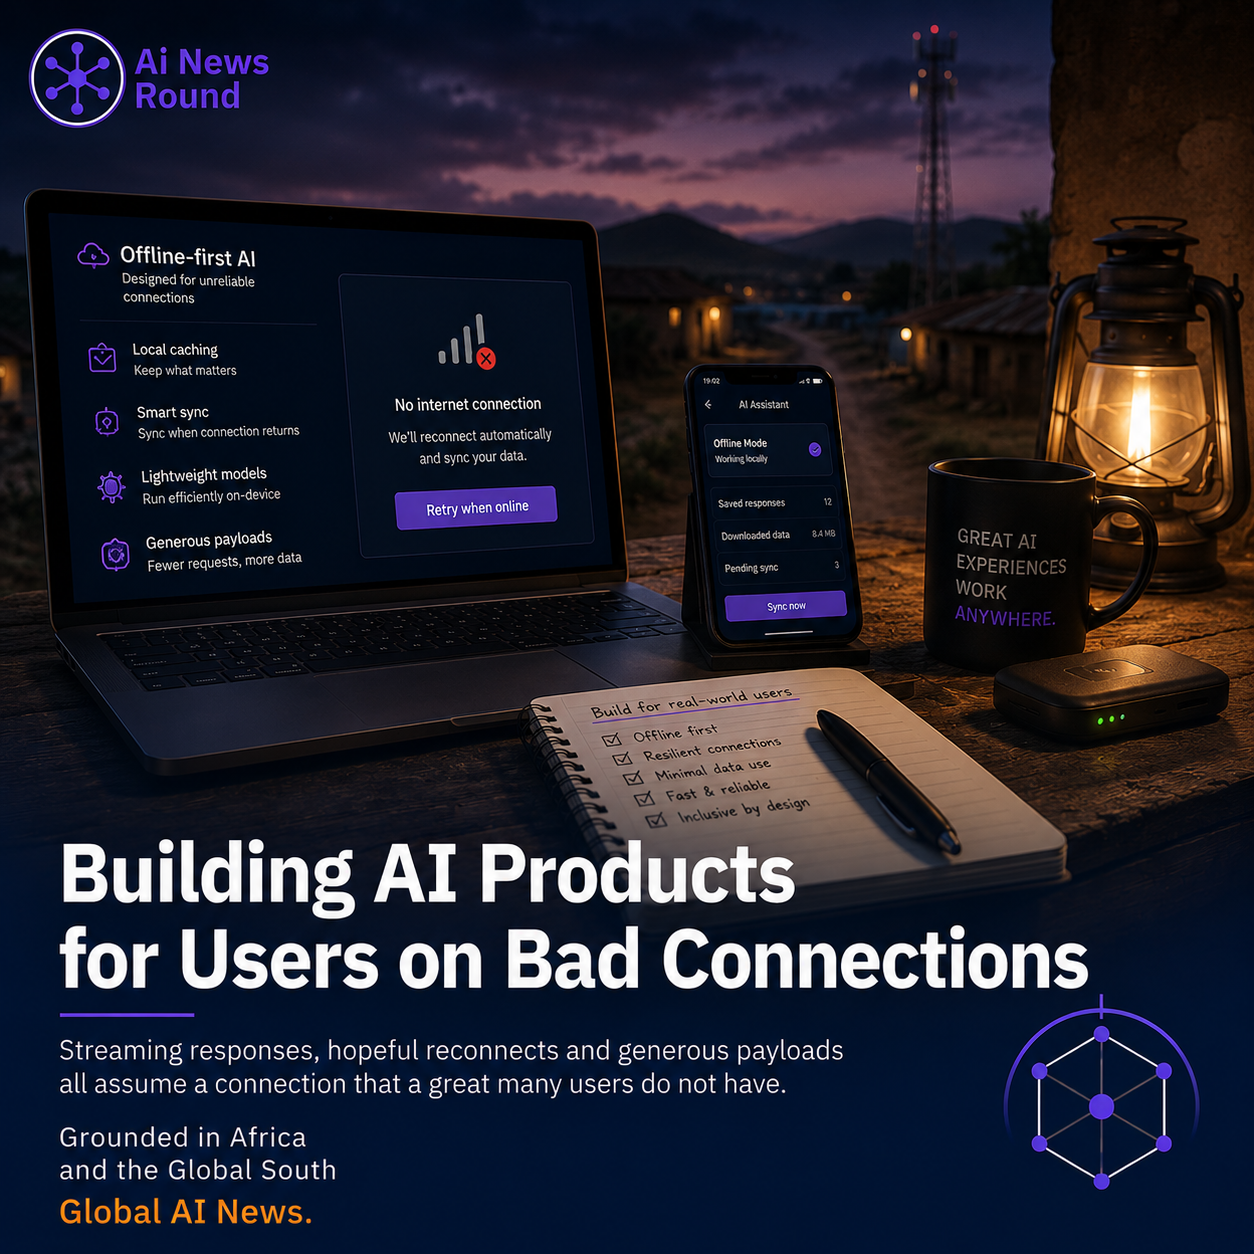
Streaming responses, hopeful reconnects and generous payloads all assume a connection that a great many users do not have.
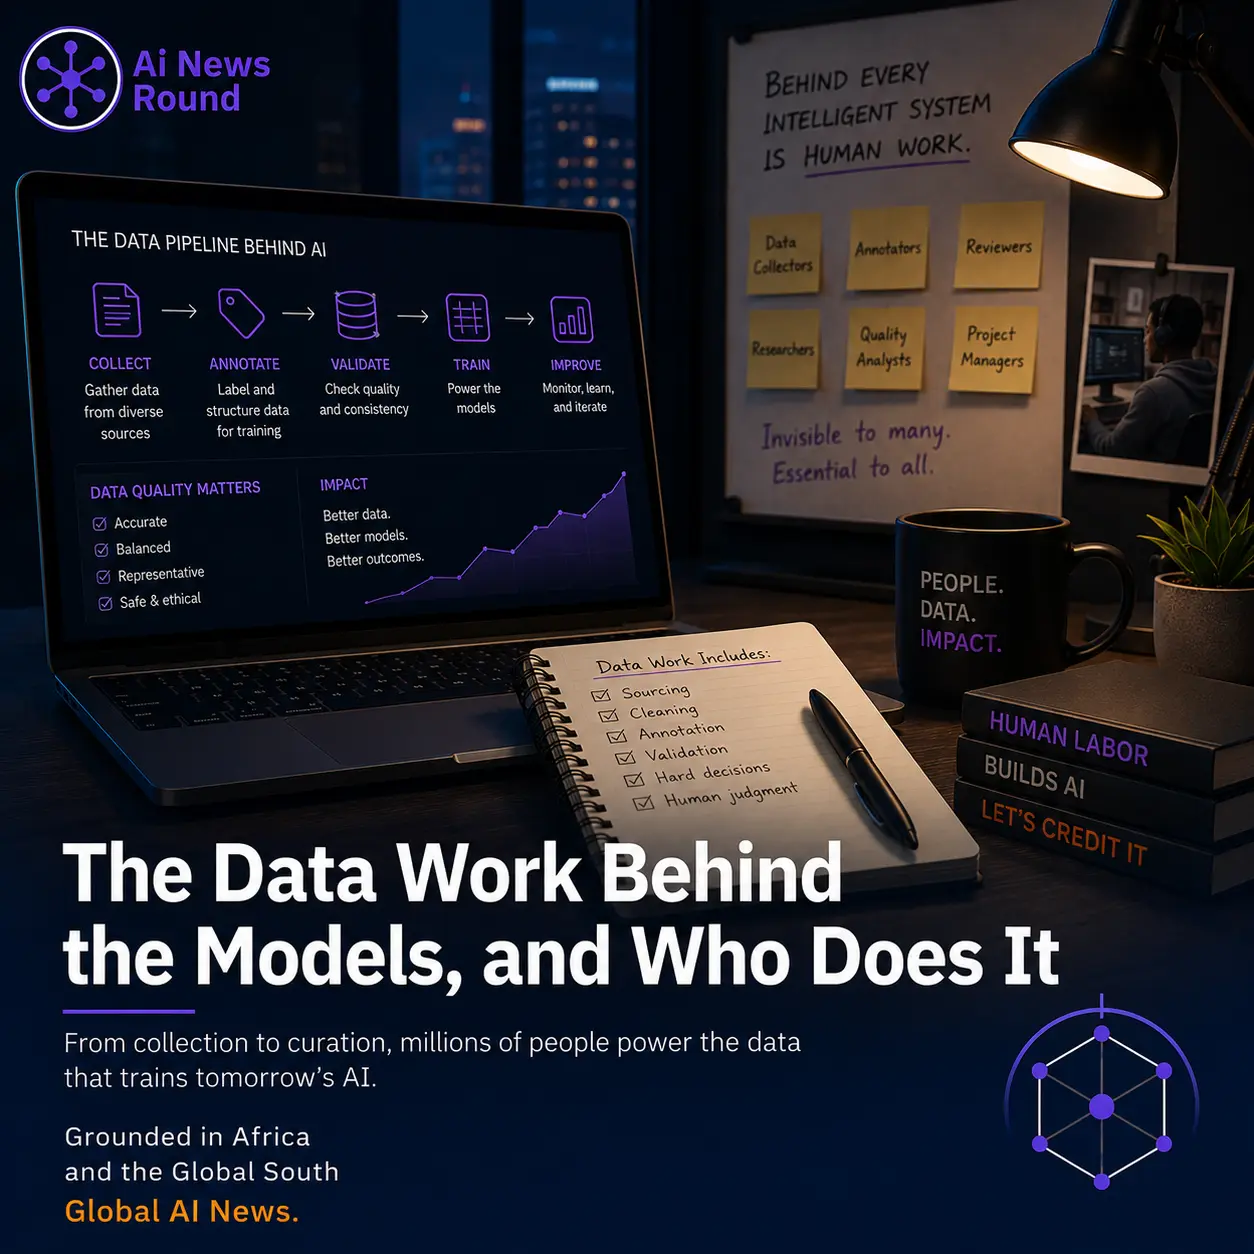
Annotation, moderation and evaluation are done by people, a great many of them in East and West Africa, and the conditions attached deserve more attention than they get.
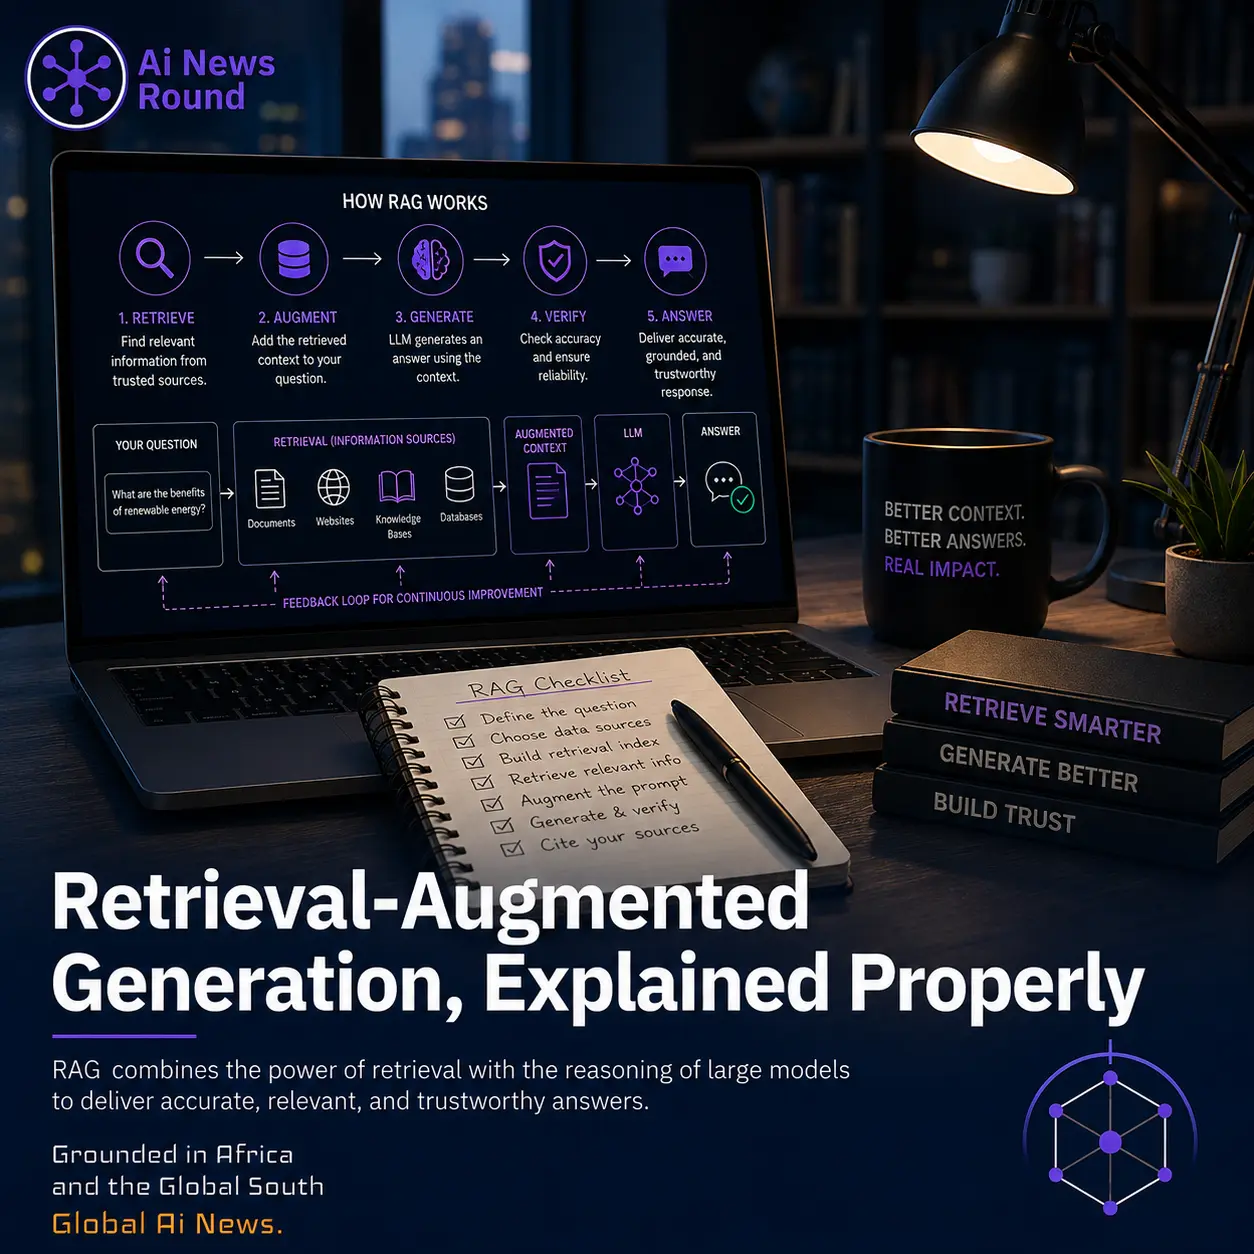
The idea is simple and the failure modes are not. Most disappointing implementations fail at retrieval, not at generation.
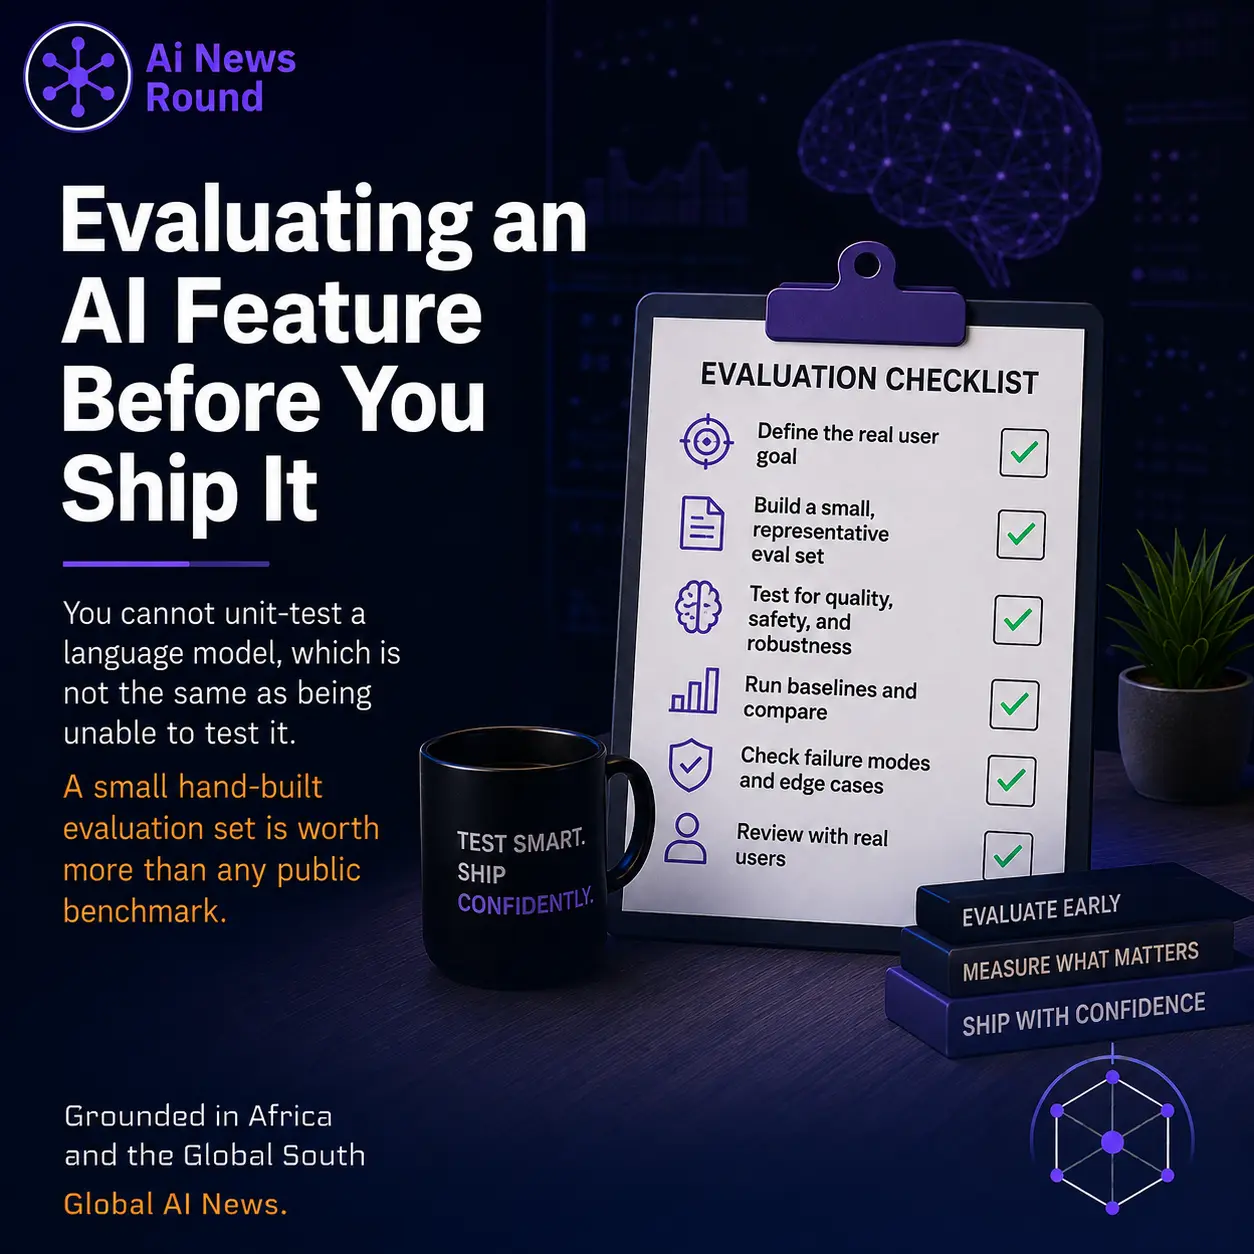
You cannot unit-test a language model, which is not the same as being unable to test it. A small hand-built evaluation set is worth more than any public benchmark.
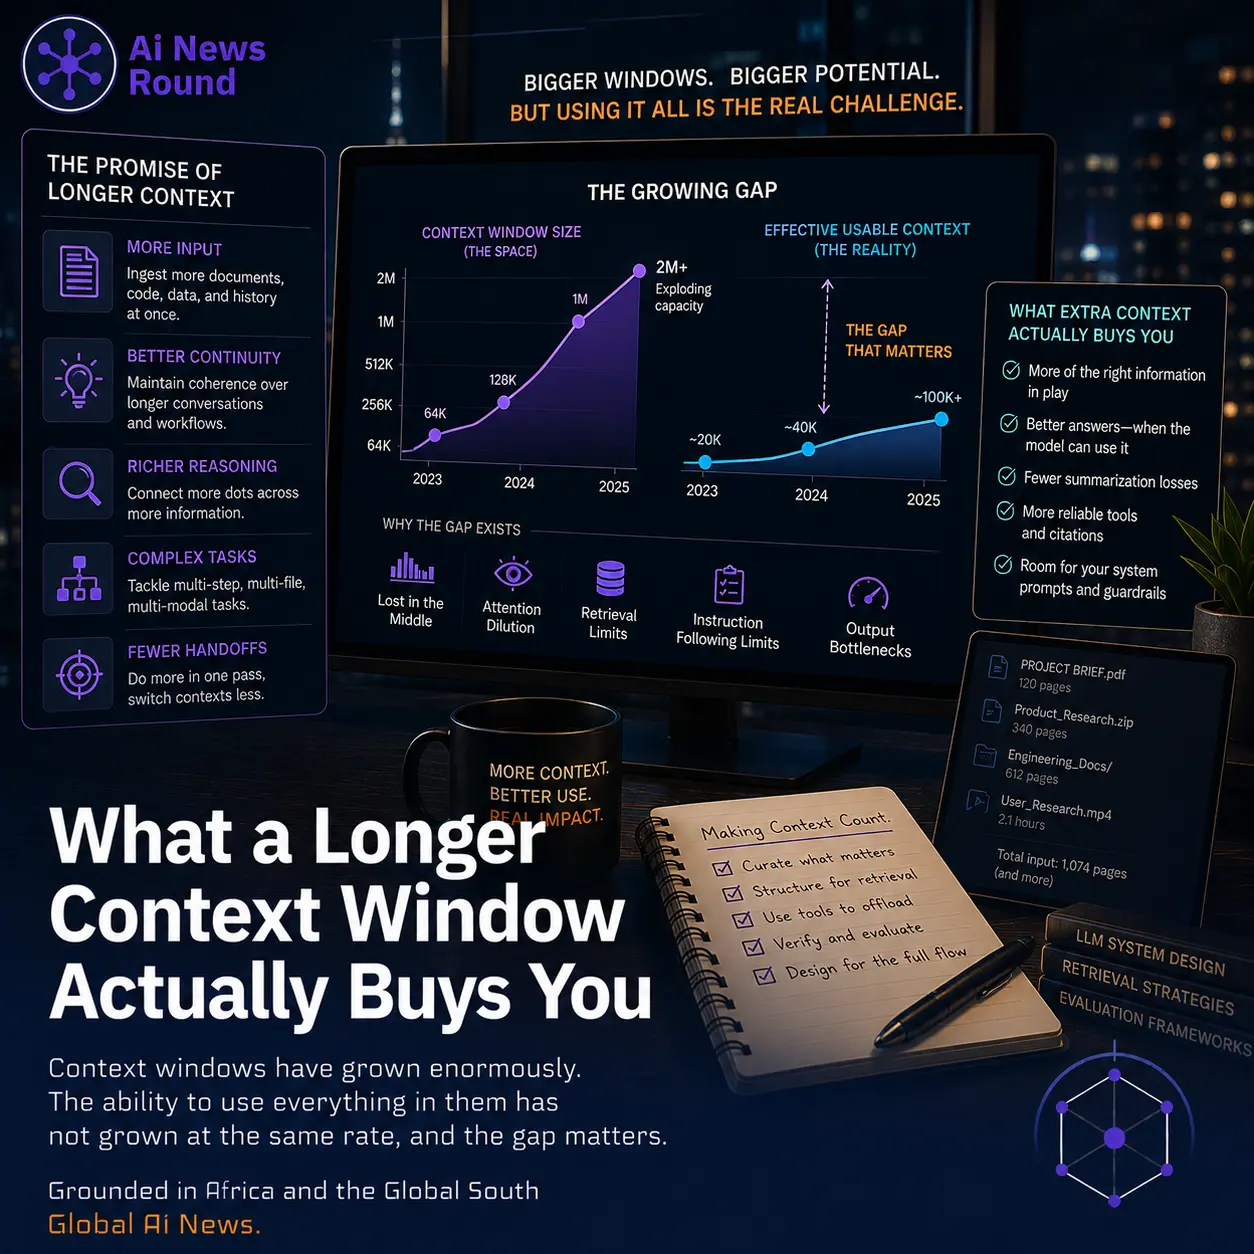
Context windows have grown enormously. The ability to use everything in them has not grown at the same rate, and the gap matters.
Get a notification when something new is published.
Done. To stop them later, use the notification settings for this site in your browser.