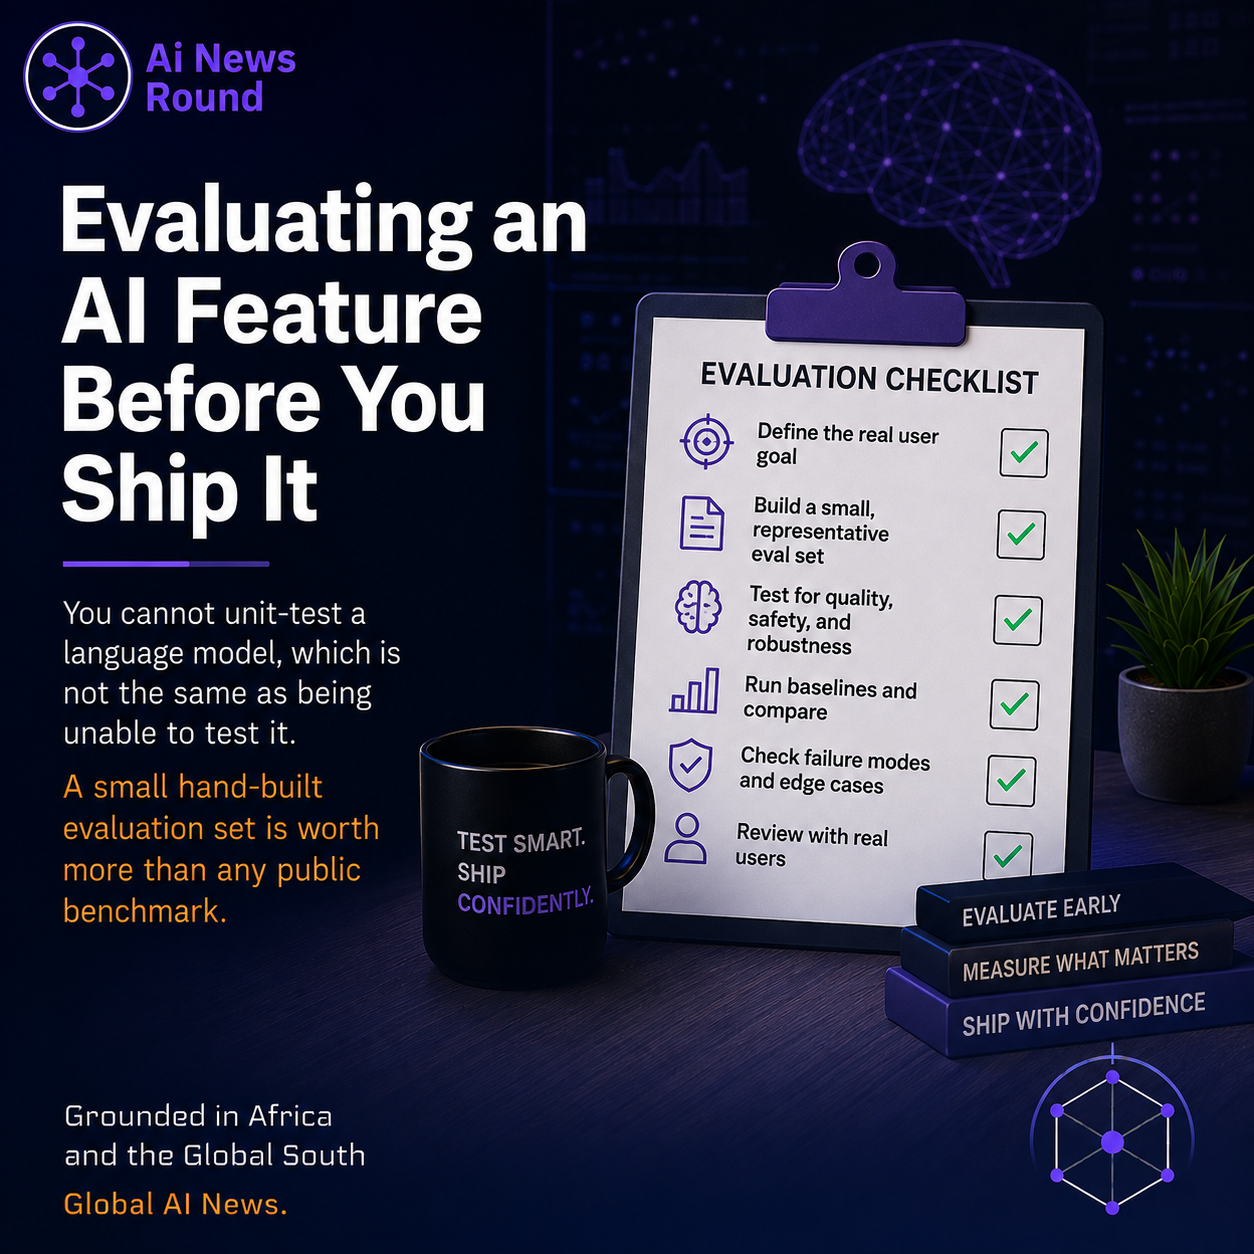
Teams shipping language model features frequently have no test for them beyond somebody trying a few prompts and being satisfied. That is not because evaluation is impossible. It is because the familiar tools do not apply and nobody built the replacement.
Build the set from real failures
Start with fifty to a hundred real examples of the task, with the answer you would accept written down. Draw them from what users actually ask rather than what you imagine they will, and weight them towards the cases that have gone wrong. This is a couple of days of unglamorous work and it converts every subsequent prompt change from a guess into a measurement.
Grade what the task actually requires
Extraction can be graded exactly — the field is right or it is not. Classification has standard measures. Open-ended generation is harder, and the workable approaches are a checklist of properties the answer must have, or another model grading against a rubric with a sample checked by a person to confirm the grader is sane. Scoring free text against a single "correct" answer is the approach that looks rigorous and measures very little.
Test the things that break in production
Empty input. Enormous input. A different language. An instruction embedded in user-supplied content trying to override yours. A question just outside what the system is meant to handle. These are where a feature that demonstrated beautifully falls over, and none of them appear in a happy-path test set.
Run it in the pipeline
A prompt is code and a model version is a dependency. Both change behaviour, and both should be gated by the same discipline as any other change. A provider updating a model underneath you is a deployment you did not perform, and an evaluation set that runs on a schedule is how you find out.