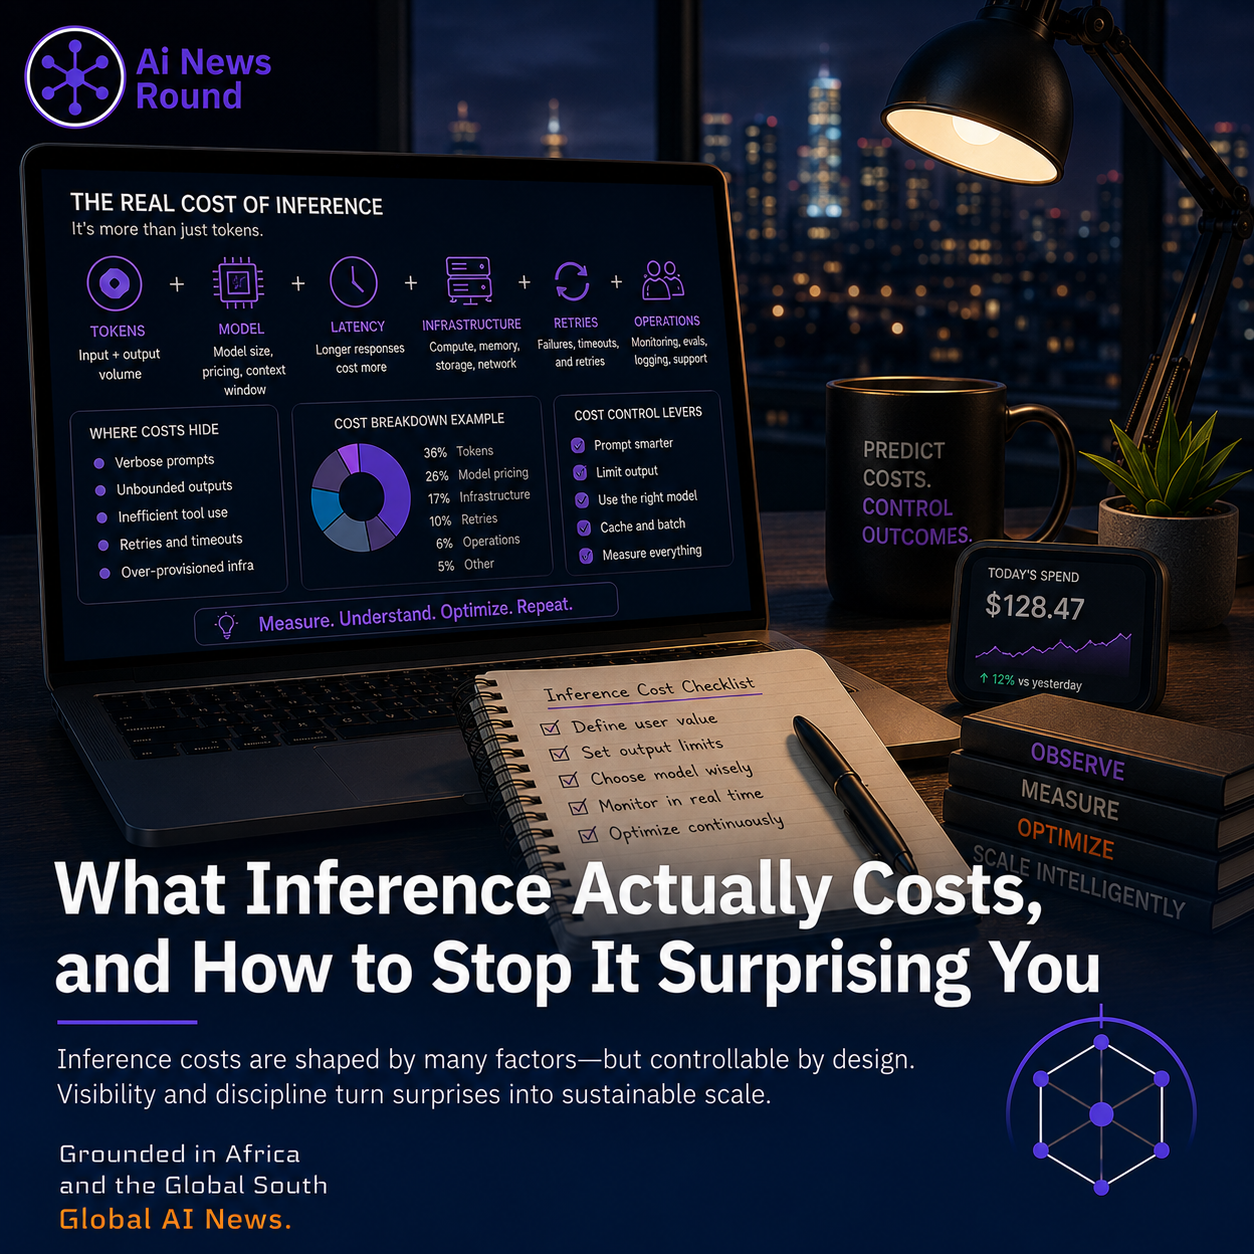
Model pricing is quoted per token, in fractions of a cent, which makes it feel negligible. It stops feeling negligible at volume, and the companies caught out are usually the ones that never modelled it before shipping.
Where the tokens actually go
Rarely the user's question. The cost sits in what is sent alongside it: a long system prompt on every call, retrieved documents pasted in whole, an entire conversation history resent with each turn, and few-shot examples that were useful during development and never removed. A request that feels like a sentence is frequently thousands of tokens.
Output is usually priced higher than input, so a model that answers at length costs more than one that answers well.
The levers, roughly in order of return
Cache aggressively — a surprising share of production traffic is repeated questions. Route by difficulty, sending the routine majority to a smaller, cheaper model and reserving the expensive one for what needs it. Retrieve tightly, passing the paragraph that matters rather than the document that contains it. Summarise long conversations rather than resending them. And set explicit output limits, because verbosity is billed.
The costs that are not on the invoice
Evaluation runs, retries after failures, and the engineering time spent on prompts all cost money and none appear as inference spend. So does the human review step that any serious deployment needs. A business case built only on the per-token price is not a business case.
The currency question
For a company earning in a currency that has weakened against the dollar, a dollar-denominated inference bill grows in local terms without a single extra request. That is an argument for open-weight models running on infrastructure you control that has nothing to do with capability, and it is why the calculation looks different depending on where you are sitting.