The State of Large Language Models in 2025: What Has Actually Changed
Context windows grew, prices fell, and the benchmark scores moved less than the marketing implies. A look at which changes are real and which are rounding errors.
The AI News Round editorial desk. Bylines are replaced with the reporting journalist once a story is commissioned — this account exists so the site has a working author profile before the newsroom is staffed.
Context windows grew, prices fell, and the benchmark scores moved less than the marketing implies. A look at which changes are real and which are rounding errors.
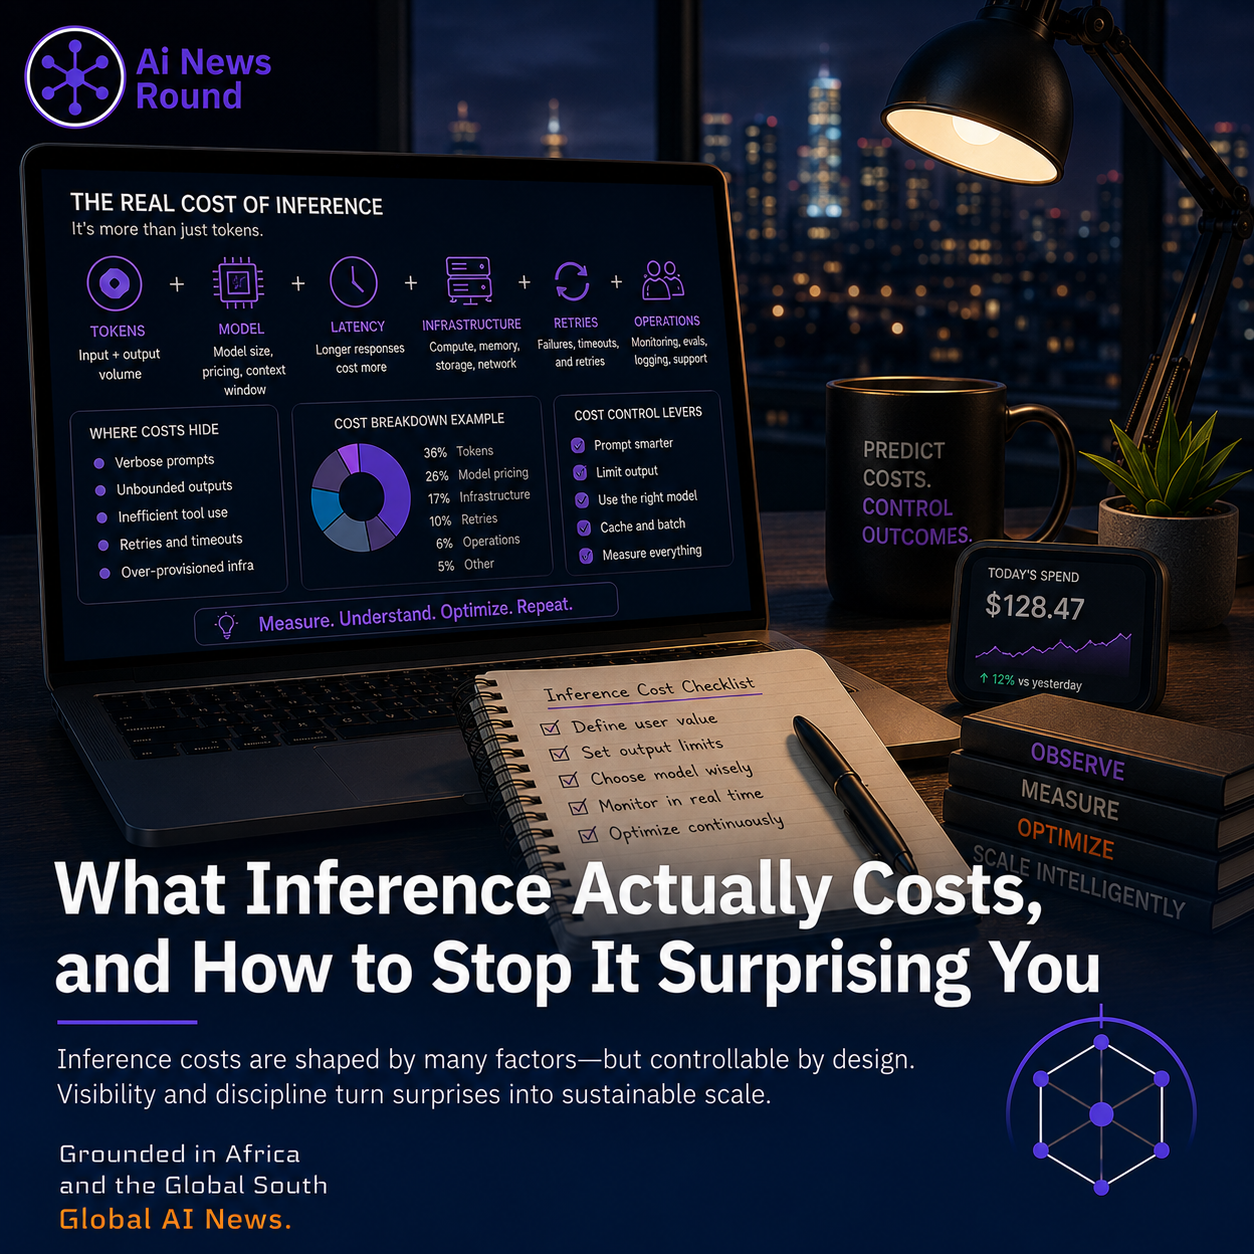
Per-token pricing looks trivial until it multiplies by traffic. The bill is controllable, and most of the control is in decisions made early.
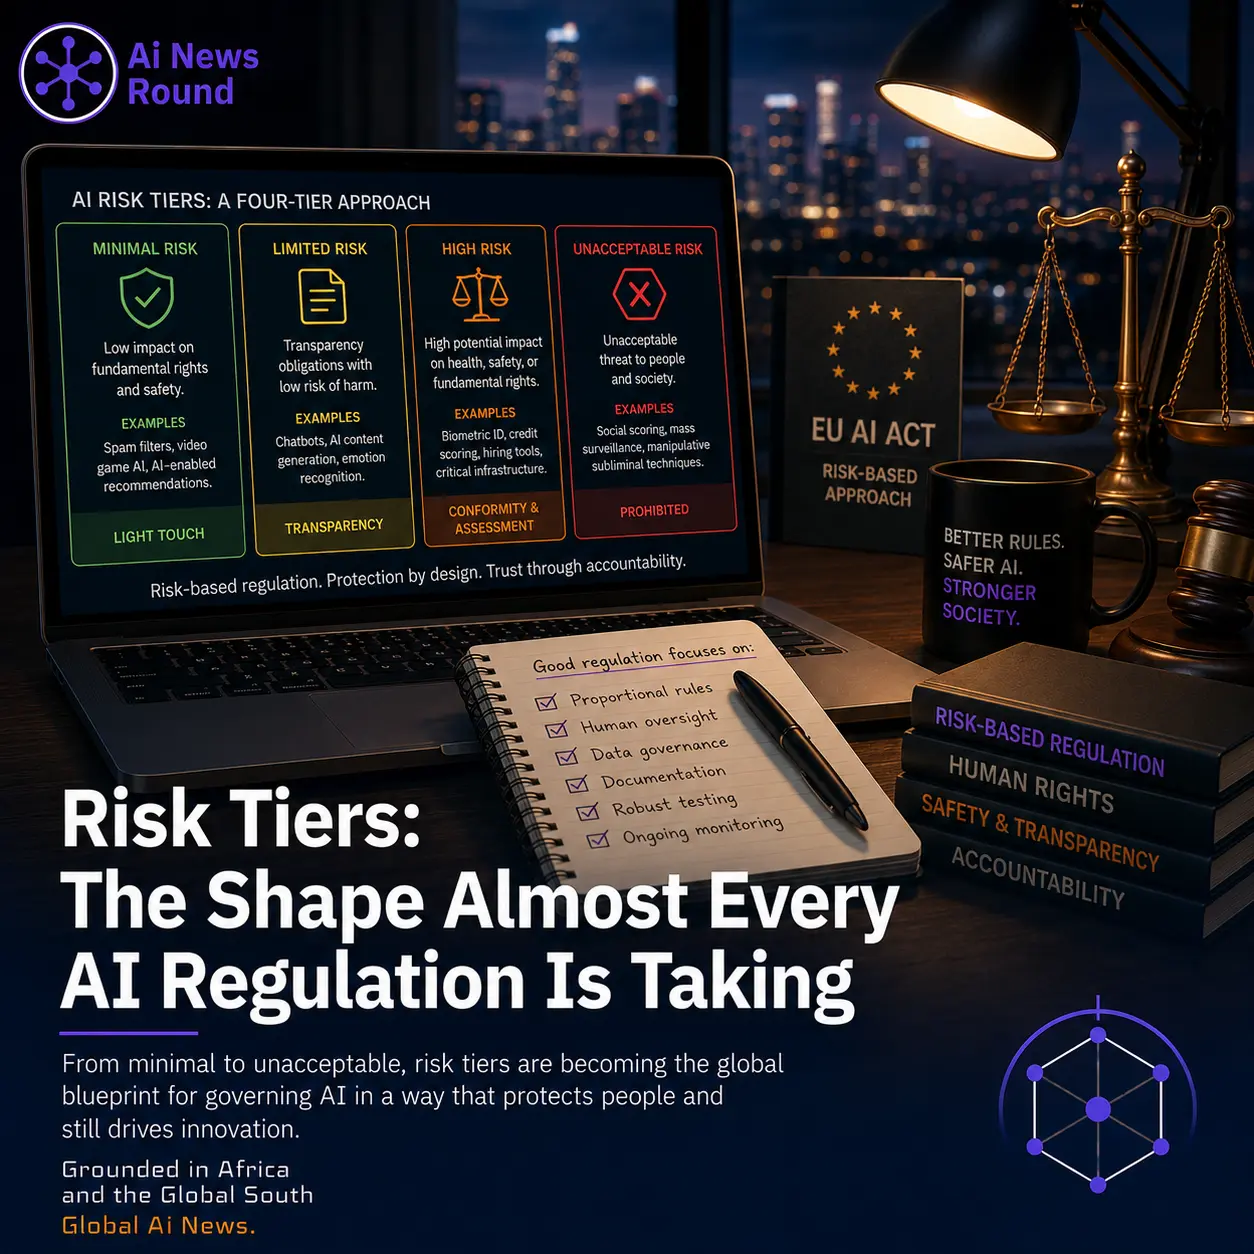
Jurisdictions differ on the detail and agree on the structure: obligations scale with what the system is used for, not with how it was built.
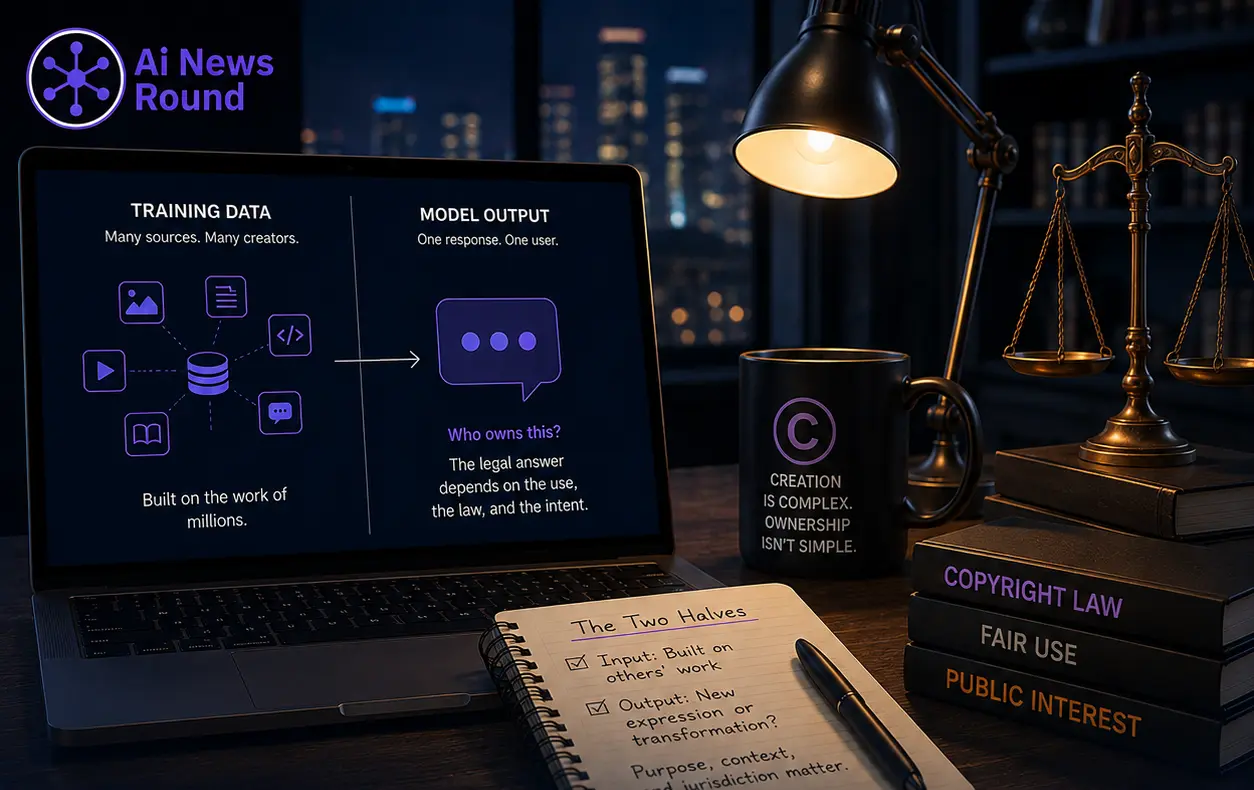
There are two separate legal arguments running, they have different answers, and conflating them is why the debate goes in circles.
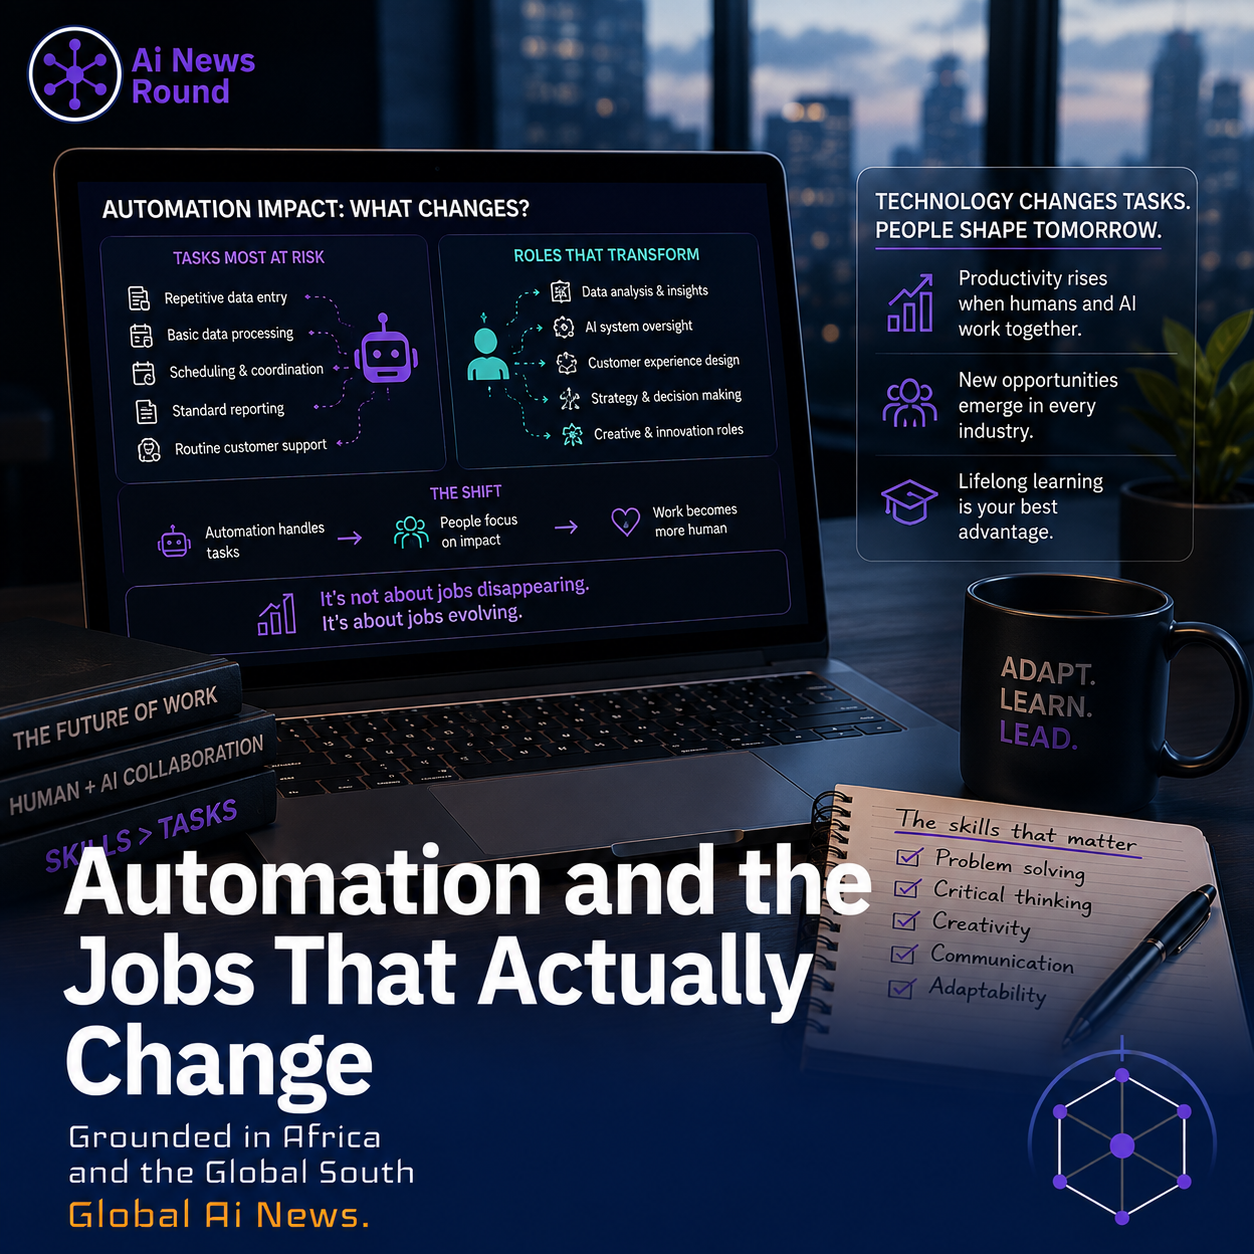
The useful unit of analysis is the task, not the occupation. Almost no job is fully automatable, and almost every job contains tasks that are.
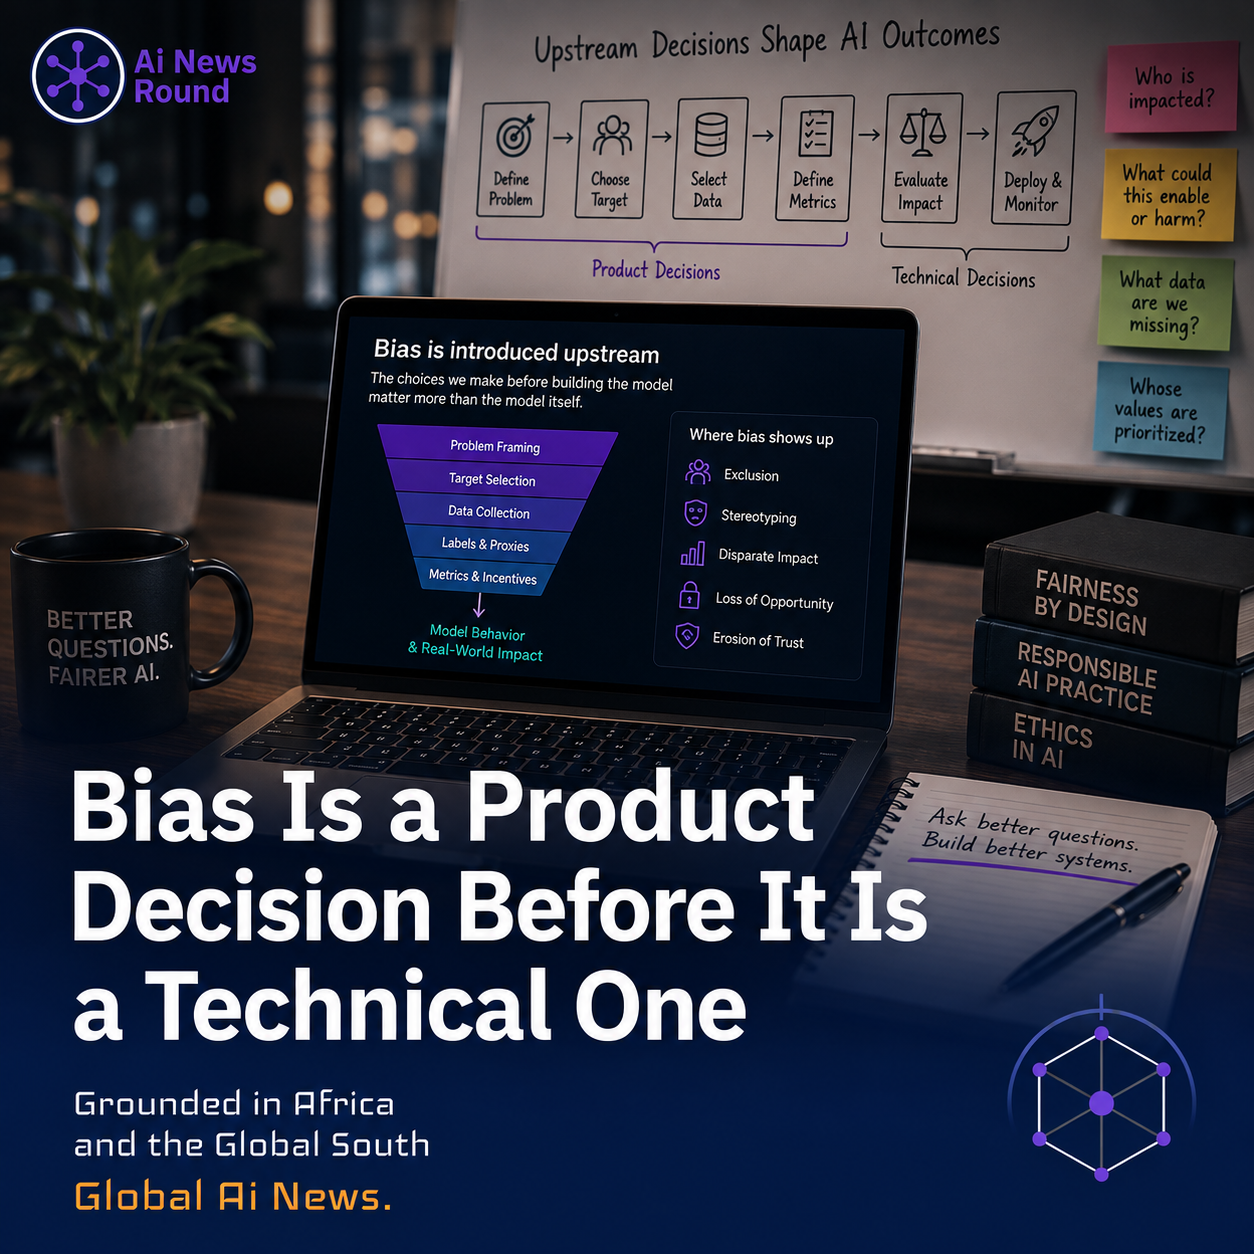
Most of the harm attributed to biased models is decided upstream: what the system is asked to predict, and what data was available to predict it from.
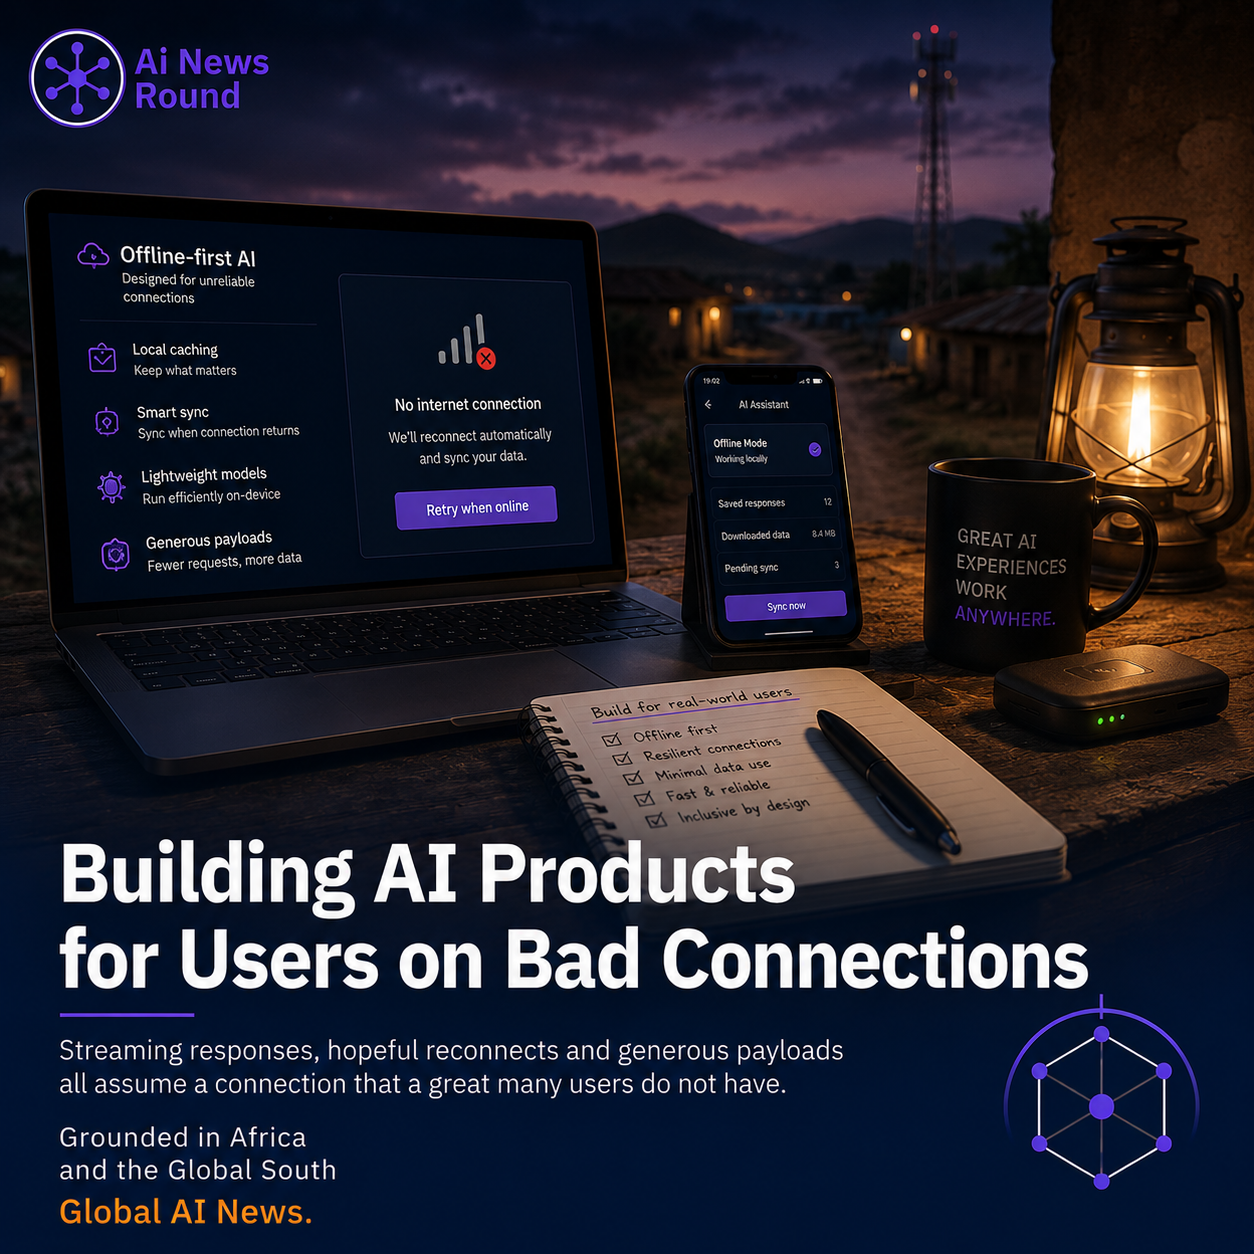
Streaming responses, hopeful reconnects and generous payloads all assume a connection that a great many users do not have.
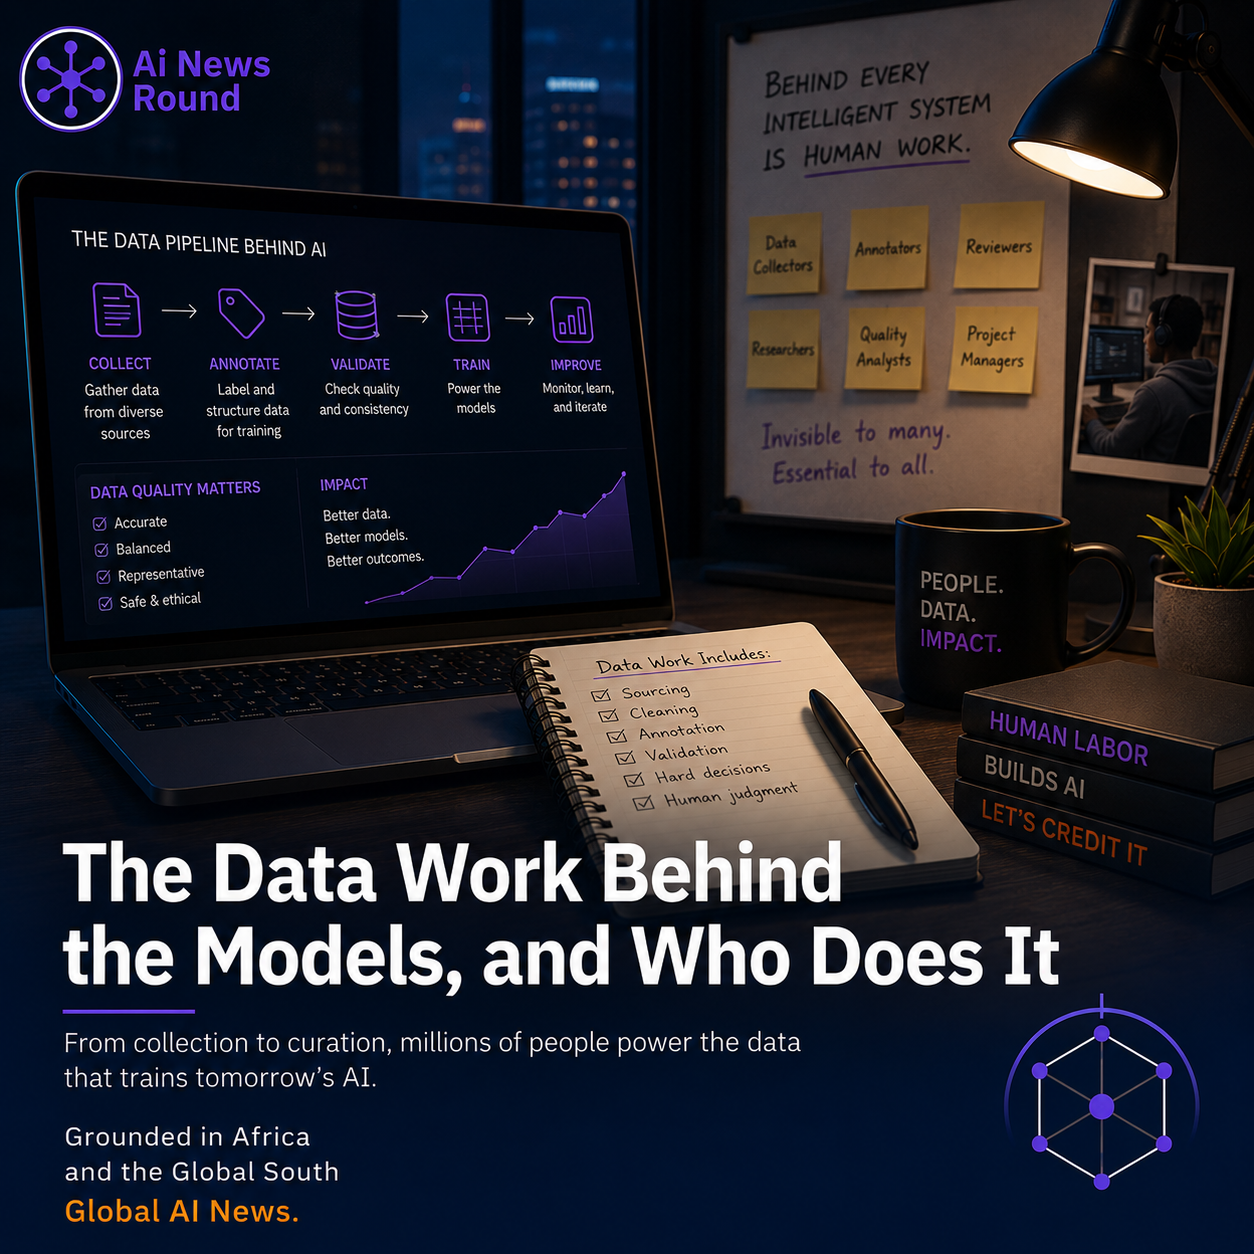
Annotation, moderation and evaluation are done by people, a great many of them in East and West Africa, and the conditions attached deserve more attention than they get.
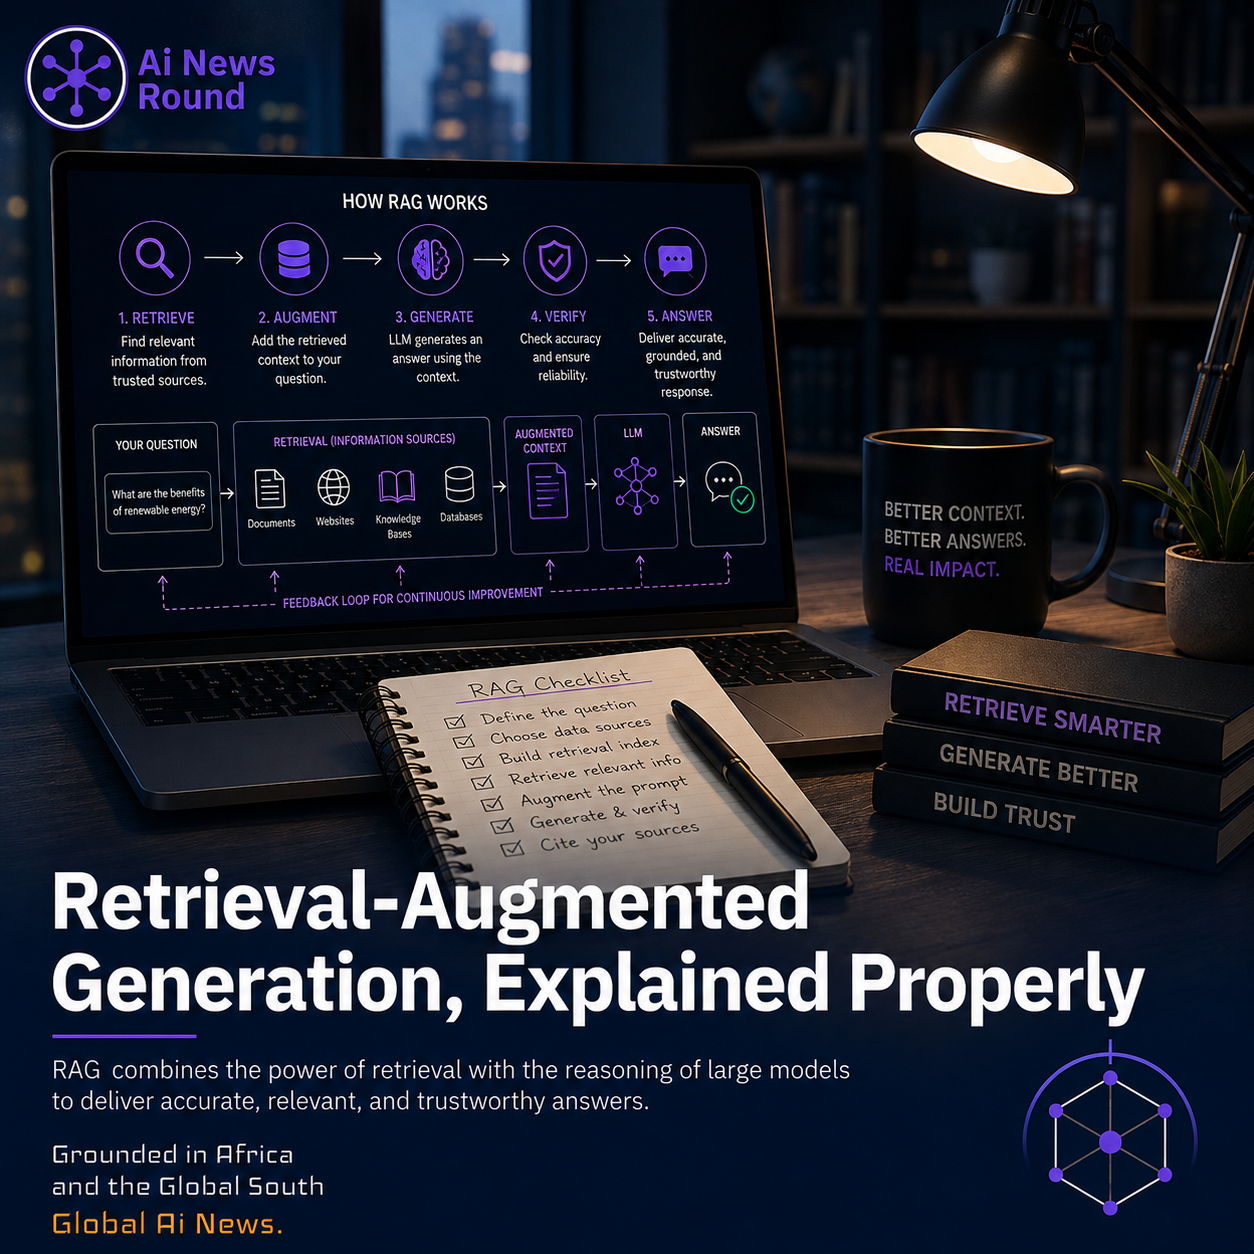
The idea is simple and the failure modes are not. Most disappointing implementations fail at retrieval, not at generation.
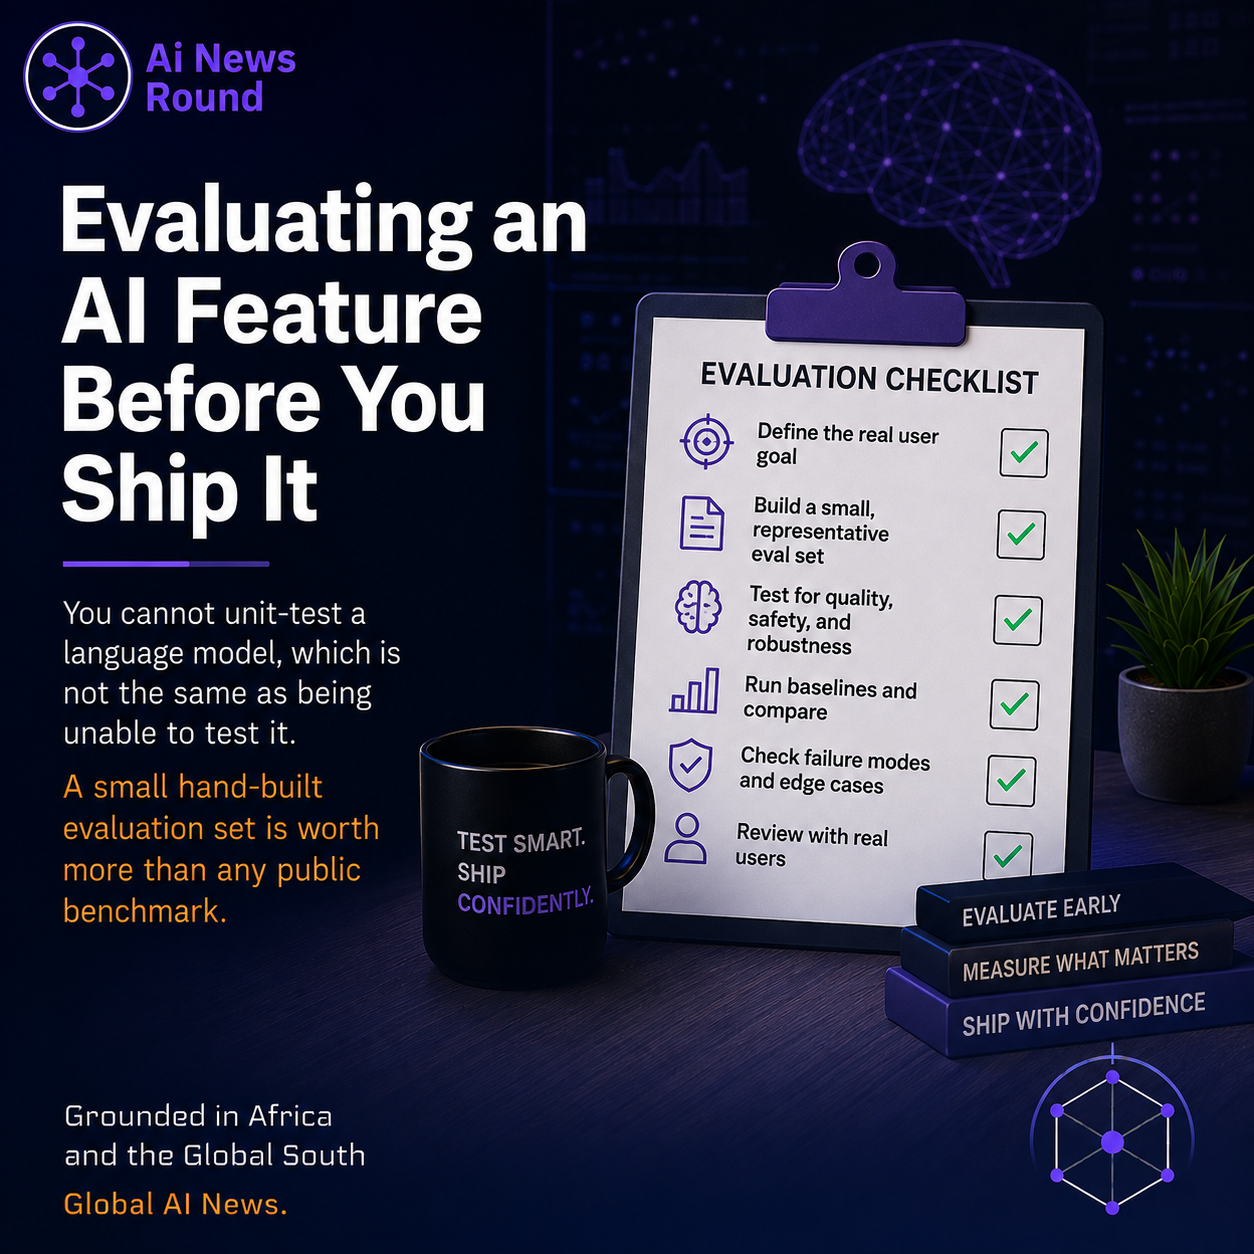
You cannot unit-test a language model, which is not the same as being unable to test it. A small hand-built evaluation set is worth more than any public benchmark.
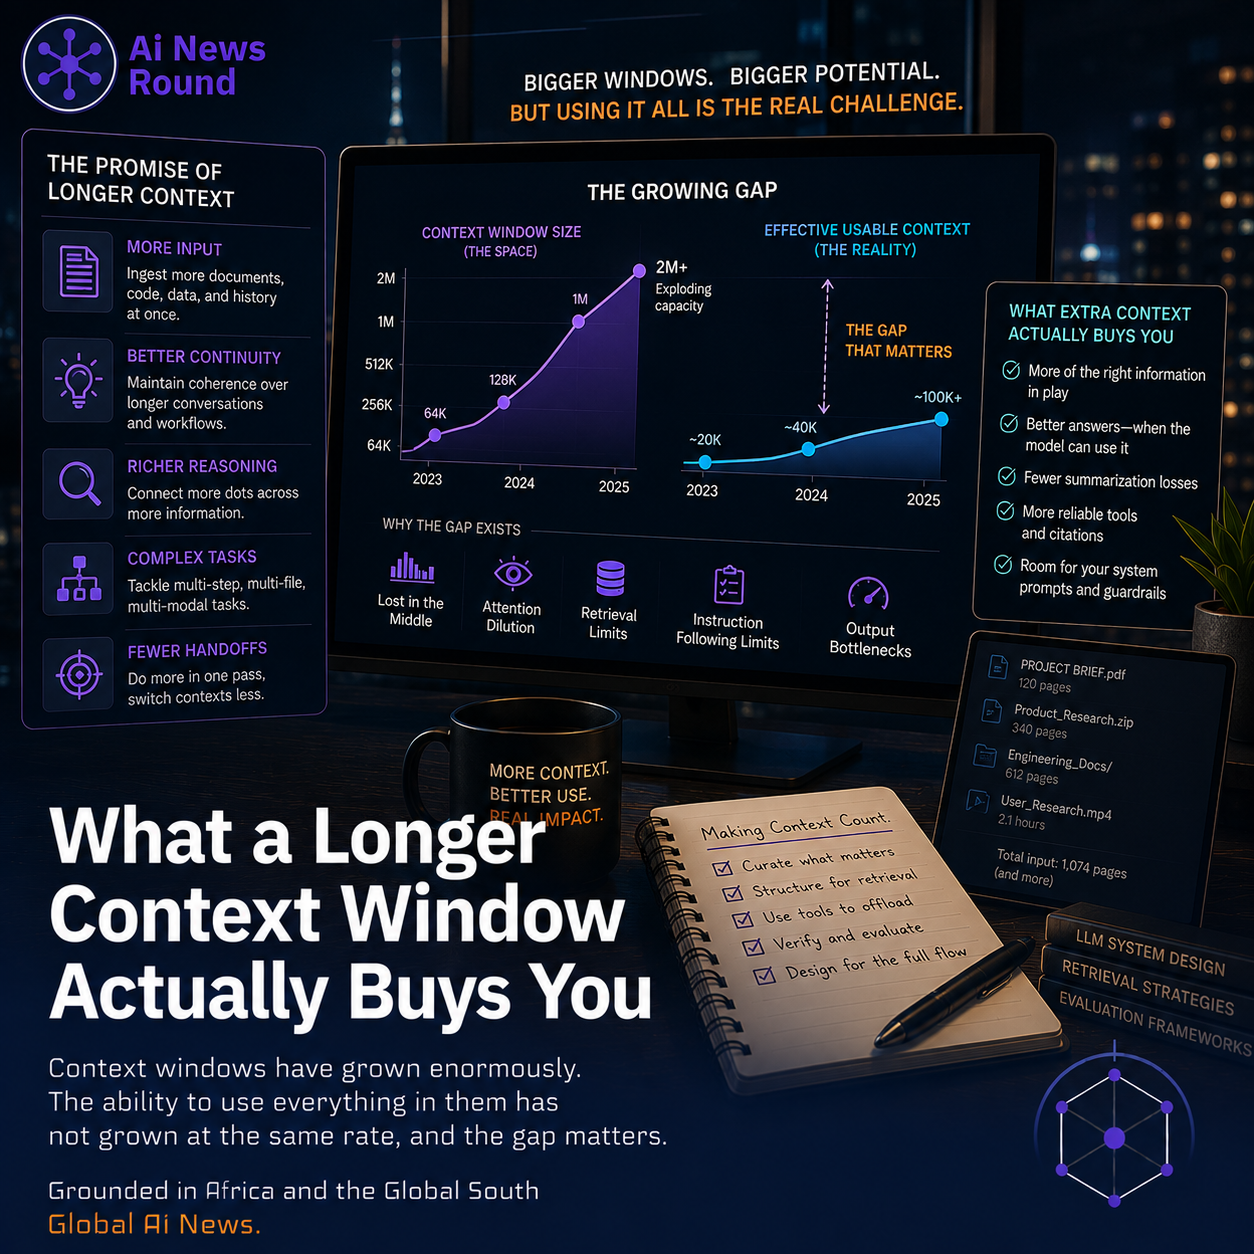
Context windows have grown enormously. The ability to use everything in them has not grown at the same rate, and the gap matters.
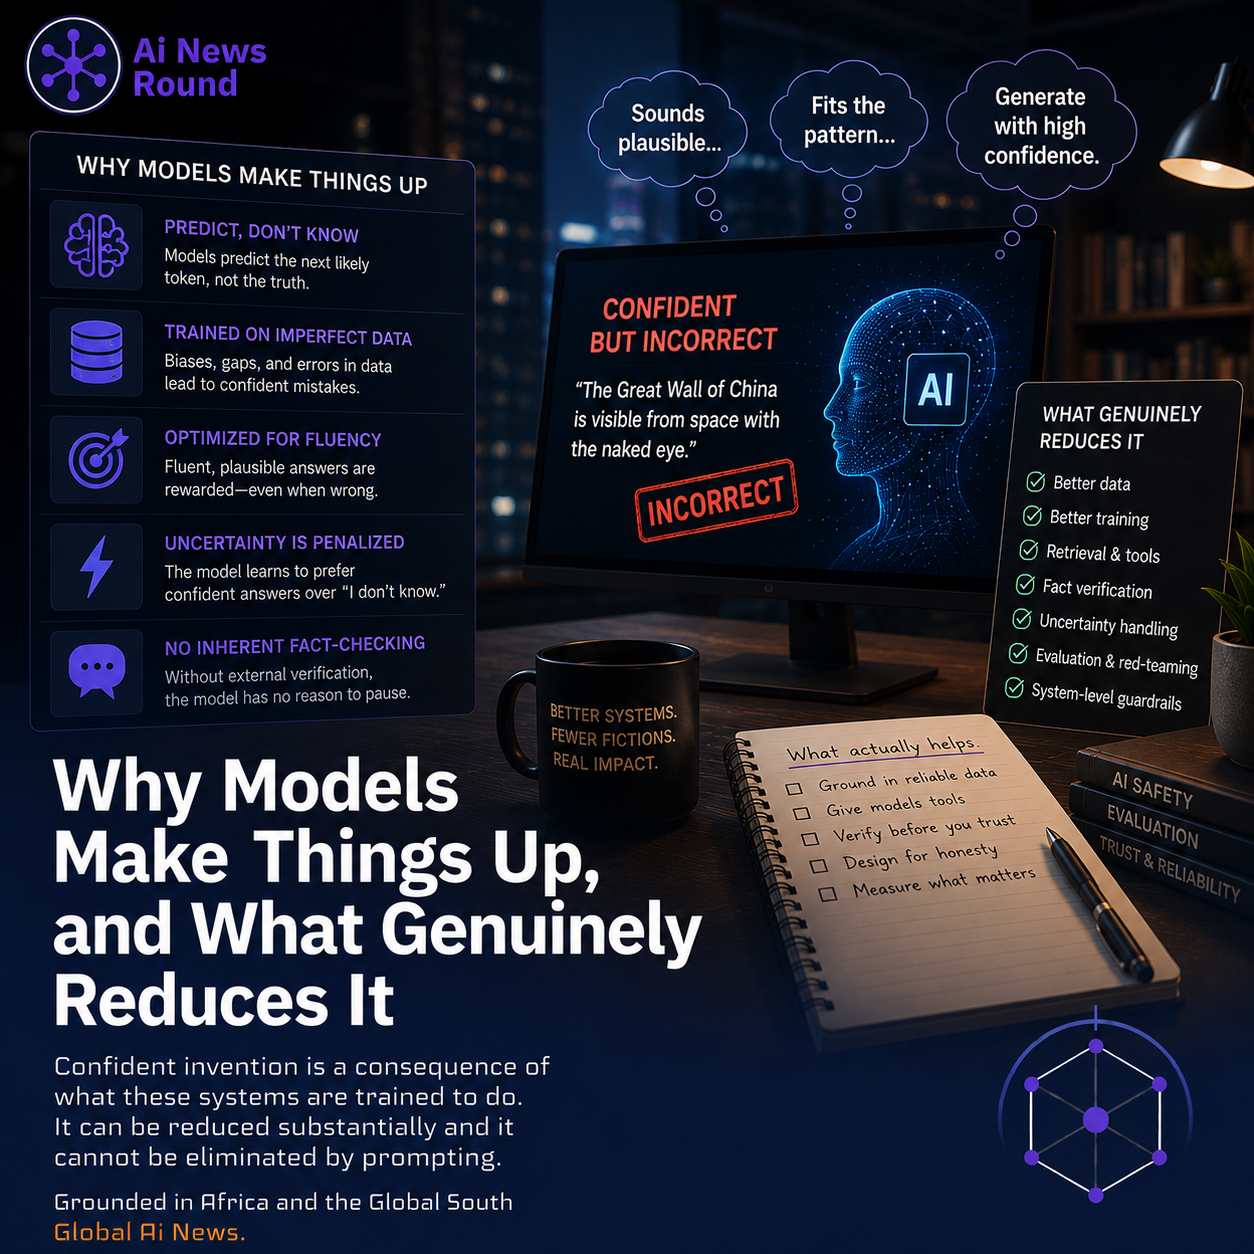
Confident invention is a consequence of what these systems are trained to do. It can be reduced substantially and it cannot be eliminated by prompting.
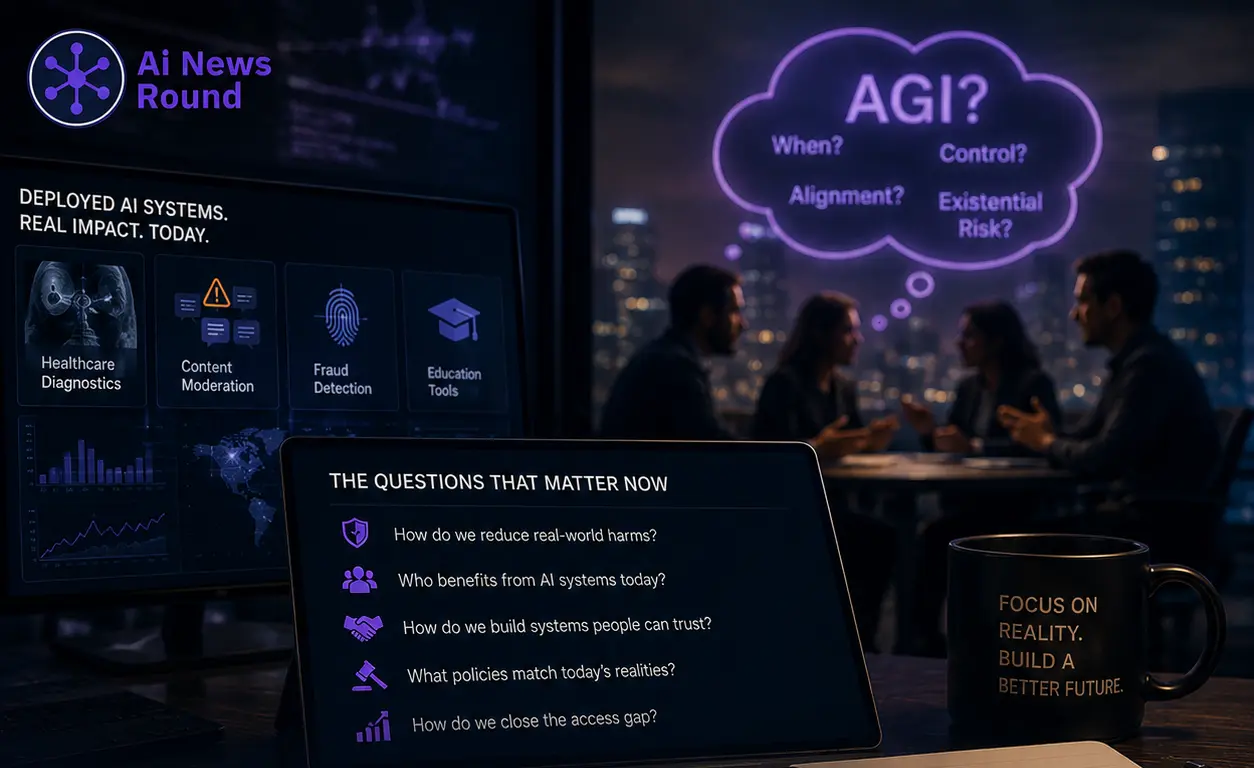
Arguing about a hypothetical future system is more comfortable than arguing about the deployed ones. That is largely why it is so popular.
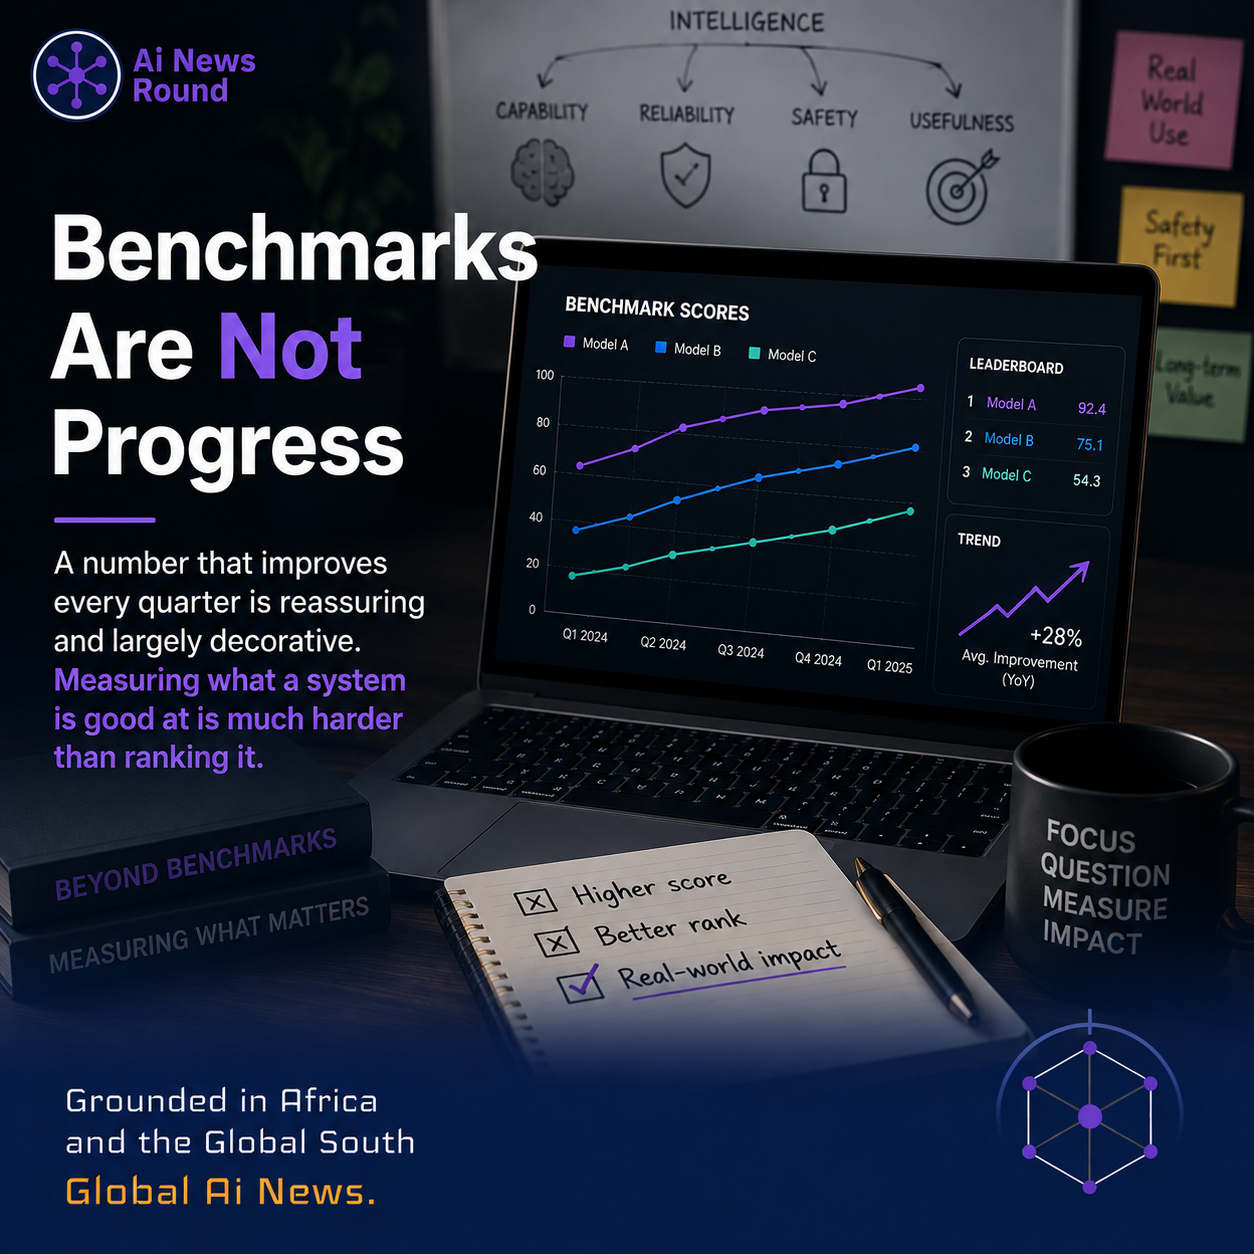
A number that improves every quarter is reassuring and largely decorative. Measuring what a system is good at is much harder than ranking it.