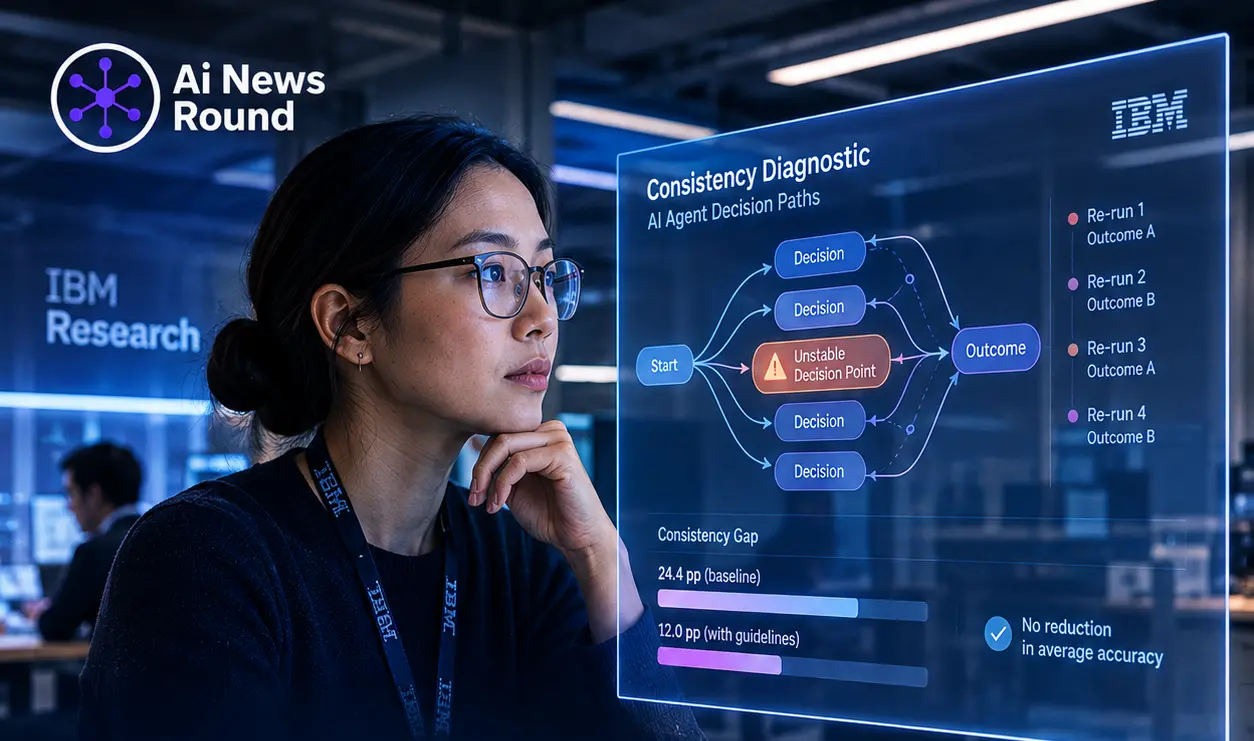
The AI Agent Reliability Gap
Artificial intelligence benchmarks frequently rely on average success rates, known as Mean@k, to measure model capabilities across multiple executions. However, this aggregate metric often masks severe inconsistency during deployment. For instance, a ReAct agent driven by GPT-4.1 achieved a 77.4 per cent average pass rate on the AppWorld benchmark across five repetitions. Despite this seemingly high score, the agent succeeded across all five consecutive runs on only 53.0 per cent of the tasks, revealing a massive 24.4 percentage point consistency gap.
Detailed technical analysis published on Hugging Face demonstrates that this divergence arises because intermediate decisions depend heavily on token probability distributions. On hosted API endpoints, slight fluctuations in these probability distributions can alter execution outcomes across identical runs, leading to variable paths even when using zero temperature settings.
Diagnosing Decision Instability
To solve this issue, researchers at IBM Research developed a two-stage diagnostic framework within their open-source ALTK-Evolve architecture. The system identifies points of structural instability without requiring internal access to model logits, extra environment rollouts, or ground-truth annotations.
- Detection Phase: A tool called the Consistency Analyzer replays every recorded decision step using offline resampling, generating multiple completions per step to assign a precise uncertainty score.
- Generation Phase: High-uncertainty decision steps are converted into targeted, human-readable guidelines that are injected back into the agent prompt context during subsequent execution runs.
Experimental Results and Performance
In evaluations across AppWorld benchmark tasks, injecting these consistency guidelines narrowed the consistency gap from 24.4 percentage points to 12.0 percentage points. Aggregate success on five consecutive runs rose significantly from 53.0 per cent to 69.0 per cent, whilst overall average accuracy reached 81.0 per cent. Similar methodological benchmarks covering system evaluation were previously explored in our technical breakdown of AppWorld agent architectures.
Furthermore, the generated guidelines demonstrated strong generalization across similar tasks rather than merely memorizing individual trajectories. Similar-task generalization increased by 8.7 percentage points on smaller open-weights models like gpt-oss-120b, proving that addressing step-level decision uncertainty creates fundamentally more dependable AI agents across varied real-world enterprise workflows.
Underlying Root Causes and Architectural Impact
The core vulnerability in multi-step AI agent trajectories stems from step-level compounding errors. When an agent makes dozens of intermediate decisions—such as selecting tools, forming API query strings, parsing JSON responses, or determining retry loops—even a tiny probability variance at a single step can alter the entire execution path downstream. Standard evaluation protocols obscure this behavior because success on run one does not guarantee that the agent will avoid a alternative, faulty path on run two.
By utilizing the Consistency Analyzer to resample decision steps with a default setting of five completions per step, developers can isolate flat probability distributions. These flat distributions indicate points where the model is nearly torn between multiple actions, making it exceptionally vulnerable to subtle infrastructure-level noise, such as GPU floating-point non-associativity. Converting those specific decision moments into natural language guidelines provides the necessary context steering to anchor the agent's reasoning, effectively mitigating non-deterministic branching in mission-critical applications.